How Token Selection Works in Neural Networks: logits, Temperature, and top-p
A neural network selects the next word through logits and softmax. Temperature controls randomness: low values produce accurate answers, high values produce creative ones. Top-p filters out unlikely variants. Proper tuning of these parameters determines text quality.
AI-processed from Machine Learning Mastery; edited by Hamidun News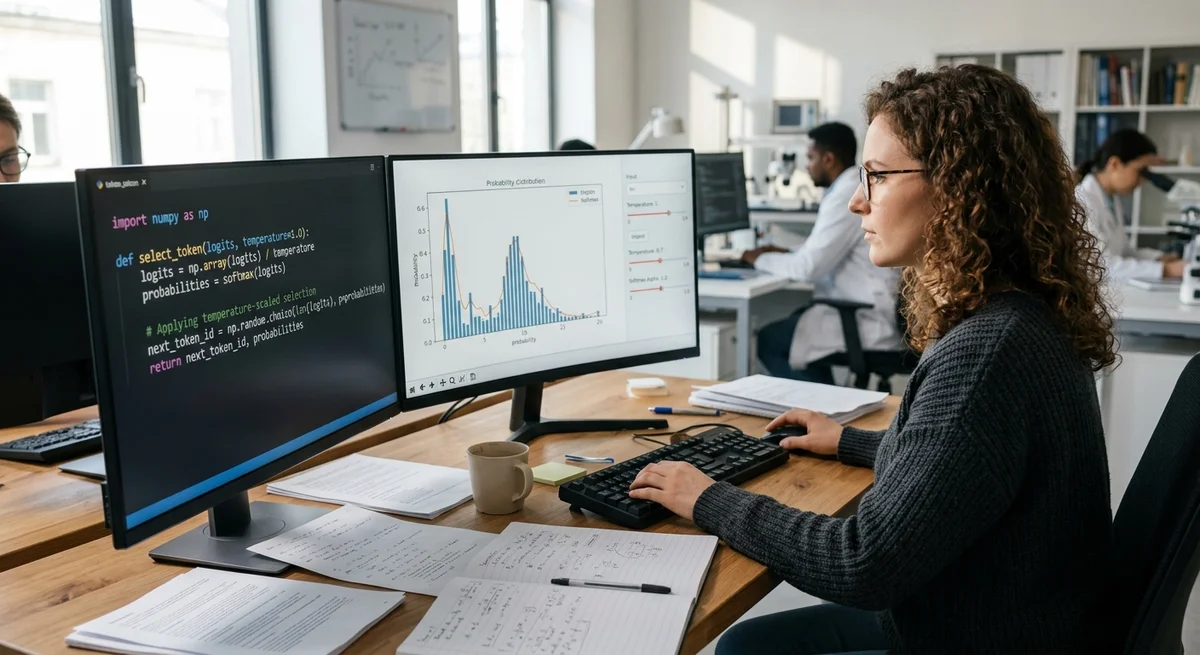
When a language model generates text, it faces a fundamental task: selecting the next word from thousands of candidates. This choice is not random but governed by probabilistic mechanisms. Understanding logits, temperature, and top-p is key to controlling LLM behavior.
What Are Logits and Softmax
A neural network computes a numerical score—a logit—for each possible token. This is the raw signal from the network's final layer. The word "creativity" might receive a logit of 5.2, while "phone" gets 2.1. The softmax function transforms these numbers into probabilities (ranging from 0 to 1) that sum to 1.
Imagine: a model processes "machine learning is". It computes logits for all vocabulary words. After softmax, you get a distribution: "science" = 35%, "art" = 8%, "penguin" = 0.001%. The model randomly samples from this distribution—frequently selecting likely options, rarely selecting unlikely ones.
Temperature: The Behavior Regulator
Temperature is a multiplier applied to logits before softmax. The math is simple, but the effect is powerful:
- T < 1 (for example, 0.3) — sends the model to the "cold" side. The distribution sharpens, unlikely options receive negligible probabilities. The model selects almost deterministically; answers are predictable and precise. Ideal for code, facts, instructions.
- T = 1 — standard behavior, logits are used as is
- T > 1 (for example, 1.5–2.0) — sends the model to the "hot" side. The distribution becomes more uniform; unlikely options get a chance. The model samples more randomly. Ideal for creative writing, but risks generating errors or hallucinations. High temperature makes the model adventurous; low temperature makes it conservative.
Top-P: Intelligent Sampling
Top-p (nucleus sampling) solves a problem: how to prevent the model from generating complete nonsense while still leaving it freedom? The algorithm sorts tokens by probability and selects enough top tokens until their cumulative probability reaches p (typically 0.9).
Example: if top-p = 0.9 and the distribution is:
- "science" = 40%
- "path" = 30%
- "knowledge" = 15%
- "freedom" = 10%
- "penguin" = 5%
The model will take the first four options (40+30+15+10=95%) and discard the "penguin". Top-p is dynamic: in one context it may select 5 options, in another it may select 200.
What Does This Mean
These three parameters are not magic but tools of control. Developers choose temperature and top-p depending on the task: code generation requires low temperature (reliability matters more than creativity), while writing a story demands high temperature (for diversity). Understanding these mechanisms transforms working with LLMs from a black box into an engineering task.
Key Questions Answered
What Are Logits and Softmax?
A neural network computes a numerical score—a logit—for each possible token. This is the raw signal from the network's final layer. The word "creativity" might receive a logit of 5.2, while "phone" gets 2.1. The softmax function transforms these numbers into probabilities (ranging from 0 to 1) that sum to 1. Imagine: a model processes "machine learning is". It computes logits for all vocabulary words. After softmax, you get a distribution: "science" = 35%, "art" = 8%, "penguin" = 0.001%. The model randomly samples from this distribution—frequently selecting likely options,
What are the key details on Temperature: The Behavior Regulator?
Temperature is a multiplier applied to logits before softmax. The math is simple, but the effect is powerful: T < 1 (for example, 0.3) — sends the model to the "cold" side. The distribution sharpens, unlikely options receive negligible probabilities. The model selects almost deterministically; answers are predictable and precise. Ideal for code, facts, instructions. T = 1 — standard behavior, logits are used as is T > 1 (for example, 1.5–2.0) — sends the model to the "hot" side. The distribution becomes more uniform; unlikely options get a chance. The model samples more ran
What are the key details on Top-P: Intelligent Sampling?
Top-p (nucleus sampling) solves a problem: how to prevent the model from generating complete nonsense while still leaving it freedom? The algorithm sorts tokens by probability and selects enough top tokens until their cumulative probability reaches p (typically 0.9). Example: if top-p = 0.9 and the distribution is: "science" = 40% "path" = 30% "knowledge" = 15% "freedom" = 10% "penguin" = 5% The model will take the first four options (40+30+15+10=95%) and discard the "penguin". Top-p is dynamic: in one context it may select 5 options, in another it may select 200.
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.