An engineer dictated a diary to an AI agent for four months — and realized memory matters more than the model
A developer dictated his personal diary via voice messages to Telegram for four months. An old gaming laptop recognized speech through faster-whisper, saved entries in Markdown, and compiled monthly reports. The turning point: AI confidently identified patterns in life without reading most of the archive. Key takeaway: in AI systems, reliable memory is more important than raw model power.
AI-processed from Habr AI; edited by Hamidun News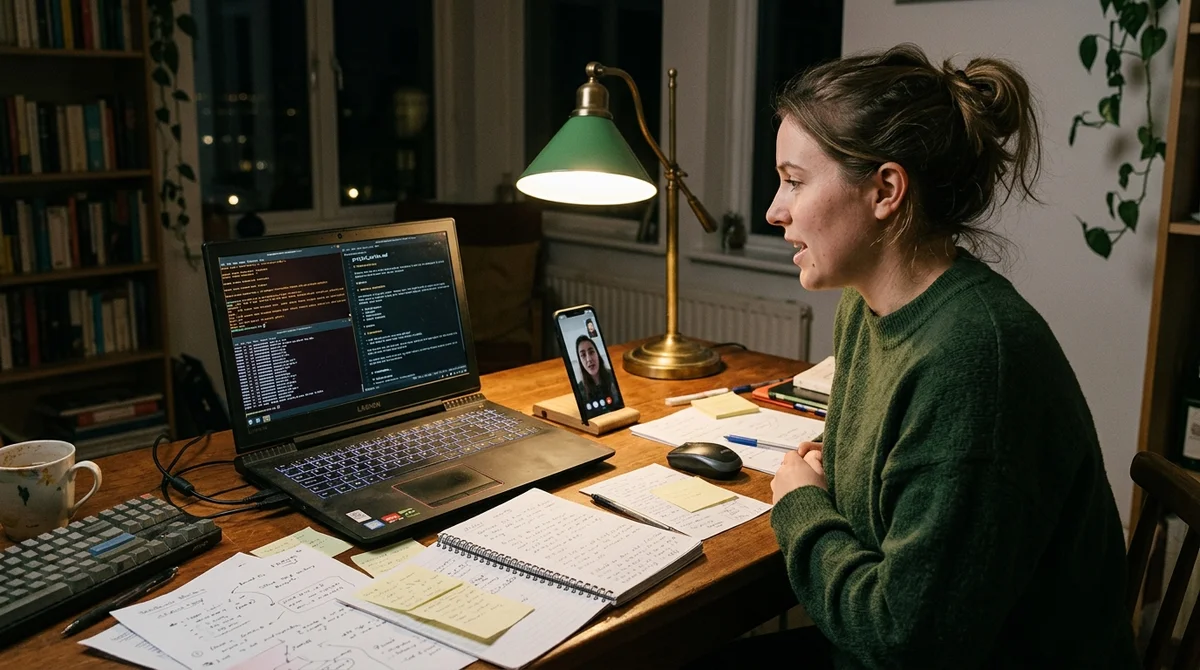
A developer spent four months daily dictating a personal diary via voice messages to Telegram and discovered something unexpected: in AI systems, reliable memory matters more than the power of the model itself.
How the System Works
The scheme appears simple at first glance: voice messages in Telegram → speech recognition via faster-whisper on an old gaming laptop → save to Markdown files → AI agent collects monthly reports and identifies patterns in the user's life. Everything runs locally, without cloud services or paid APIs. This is a fundamental part of the architecture: the system must work every day without dependence on external services and their failures. The old gaming laptop handles it fine — faster-whisper is fast enough even without a top-tier graphics card. Operating costs are minimal. The main expense is requests to the LLM when generating monthly reports, but at a reasonable frequency this fits within a few dollars a month.
The Turning Point and the Main Lesson
Everything was going fine until the AI began confidently explaining "patterns" in the author's life — even though it actually hadn't read most of the archive. The agent didn't warn that the context was incomplete. It simply constructed connections where data was missing.
"The most important part of the system is not the LLM and not the
agent, but the memory you can trust," the author concludes.
This changed development priorities. Storage quality, archive coverage, indexing reliability — all of this turned out to be more important than choosing between different language models. If the agent doesn't see the full context, it will construct false patterns regardless of how powerful the underlying model is.
What Caused Problems in Practice
Four months of real-world use revealed several issues that aren't obvious in demo mode:
- faster-whisper consistently makes errors on proper names, foreign terms, and abbreviations
- Voice in noisy environments produces many artifacts — recordings need to be checked
- Markdown files without structured metadata are poorly searchable by date and topic
- An agent without access to the full archive constructs false patterns and doesn't warn about it
- Monthly reports without deduplication repeat the same topics over and over again
Some problems are solved by post-processing transcriptions. Some require rethinking the storage architecture itself.
What Can Be Redesigned
The author arrives at several specific conclusions. Transcriptions need to be enriched with metadata: date, mood, key topics — then the agent can filter needed fragments more precisely without reading the entire archive at once. The system should explicitly report what percentage of the archive was read when forming an answer. Silent hallucination is the main danger of any agent with long-term memory. It's also worth separating the "hot" memory of recent weeks and the "cold" archive, accessing it only on explicit request for historical analysis.
What This Means
Personal AI diaries are a viable format that genuinely changes reflection and self-analysis. But their value is determined not by the model, but by memory quality. Before choosing an LLM and configuring an agent, it's worth designing storage that the agent won't be able to "imaginatively complete."
- Oct 28, 2026AdaPRA lifts Qwen 80B by 24.5 points on data science leaderboards
- Oct 28, 2026AOS-Bench: Agents Separated by 0.6 Points in Isolation Deliver 54% and 68% of the Same Tasks
- Oct 28, 2026CuraLoc finds bugs in repositories with a single plan and uses 90% fewer tokens
- Oct 28, 2026Wired Tested 6 AI Agents in a Day: Dots Leads, Gemini Spark Fails at Lunch
Key Questions Answered
How the System Works?
The scheme appears simple at first glance: voice messages in Telegram → speech recognition via faster-whisper on an old gaming laptop → save to Markdown files → AI agent collects monthly reports and identifies patterns in the user's life. Everything runs locally, without cloud services or paid APIs. This is a fundamental part of the architecture: the system must work every day without dependence on external services and their failures. The old gaming laptop handles it fine — faster-whisper is fast enough even without a top-tier graphics card. Operating costs are minimal. Th
What are the key details on The Turning Point and the Main Lesson?
Everything was going fine until the AI began confidently explaining "patterns" in the author's life — even though it actually hadn't read most of the archive. The agent didn't warn that the context was incomplete. It simply constructed connections where data was missing. "The most important part of the system is not the LLM and not the agent, but the memory you can trust," the author concludes. This changed development priorities. Storage quality, archive coverage, indexing reliability — all of this turned out to be more important than choosing between different language mo
What Caused Problems in Practice?
Four months of real-world use revealed several issues that aren't obvious in demo mode: faster-whisper consistently makes errors on proper names, foreign terms, and abbreviations Voice in noisy environments produces many artifacts — recordings need to be checked Markdown files without structured metadata are poorly searchable by date and topic An agent without access to the full archive constructs false patterns and doesn't warn about it Monthly reports without deduplication repeat the same topics over and over again Some problems are solved by post-processing transcription
Build & Ship Production AI Agents Without Boilerplate Code
Start your free 72-hour trial at Hamidun Academy (academy.hamidun.com) — interactive lessons on Claude Code & Cursor, live Tech Radar, and production agent templates.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.