How Bitrix24 Built Eval and Automated Martha RAG Agent Optimization
A Bitrix24 developer explained how they constructed a comprehensive eval system for Martha AI assistant: expert and synthetic datasets, why retrieval metrics diverge from actual answer quality—and how to close the agent feedback loop so every experiment is automatically validated rather than assessed by hand.
AI-processed from Habr AI; edited by Hamidun News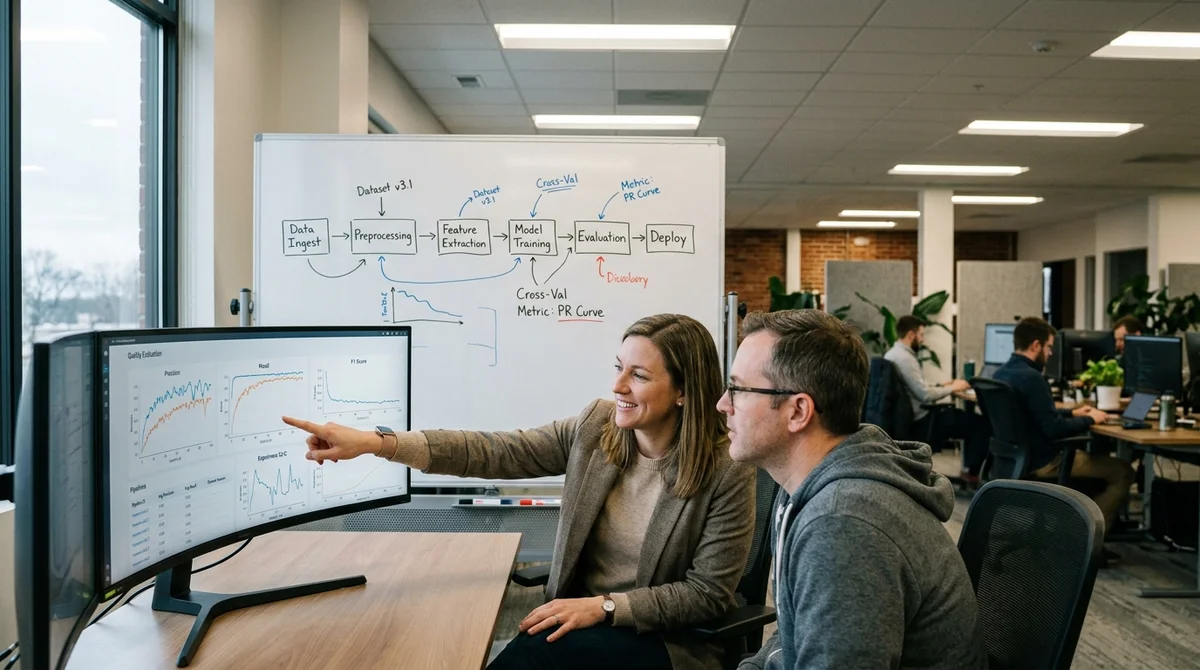
The Bitrix24 team published the second part of a technical breakdown of the RAG system for the AI assistant Martha. The first part was about the retrieval pipeline and knowledge base search. Now — about how to measure the quality of the entire chain as a whole, why separate retrieval metrics are not enough, and how to automate the experiment cycle so that every change can be verified systematically.
Retrieval Metrics Are Misleading
Classical search metrics — precision, recall, MRR — show how accurately the system finds the right documents. But they don't answer the main question: did the user receive a useful answer? The Bitrix24 developers encountered a typical production RAG trap: retrieval metrics grew from experiment to experiment, but the actual quality of Martha's answers improved disproportionately — and sometimes didn't improve at all.
Retrieval and generation are different links in the same chain. Improving search does not guarantee improving the final answer.
The solution is an end-to-end eval system that evaluates the final answer visible to the user, not just the intermediate search result.
Two Types of Datasets
The basis of the evaluation system is two datasets with fundamentally different characteristics:
- Expert dataset — questions and reference answers written manually by specialists who know the product well. Precise and reliable: if the system makes a mistake here, the problem is obvious. The downside — expensive to create, difficult to scale.
- Synthetic dataset — question-answer pairs automatically generated based on product documentation. Created quickly and in large volumes, but requires filtering: LLM generation inevitably introduces noise and artifacts.
Both datasets work together. The expert dataset covers critically important scenarios, the synthetic dataset covers the long tail of queries that can't be reached manually. This combination gives a more complete picture of quality than either approach alone.
Closed Optimization Loop
The key practical result of the second part is automation of the experiment cycle. Previously, each change in the retrieval pipeline required manual verification: run eval, collect metrics, compare with the previous version, make a decision. Slow, subjective, and doesn't scale well.
The new system closes the loop:
- change enters the pipeline
- eval automatically runs on both datasets
- metrics are compared against baseline
- regressions are fixed immediately and don't go to production
- experiment history accumulates in structured form
Essentially, it's CI/CD for answer quality. Each experiment leaves a trace, the team sees which solutions work systematically, not by chance. This is especially important when the RAG pipeline consists of several interdependent components.
When Metrics Diverge
One of the key observations in the article: retrieval metrics and final answer quality metrics can move in opposite directions — and that's normal. More accurate search sometimes returns documents that are technically relevant but don't help the LLM formulate a good answer: too long, too technical, or duplicating each other.
Conversely, less aggressive retrieval sometimes produces a better result because the context becomes more compact and cleaner for generation.
"Production RAG is constant work with retrieval, noise, and latency."
The final picture of quality is always several metrics working together. Focusing on just one means optimizing the wrong thing.
What This Means
Bitrix24's experience shows what a mature approach to production RAG looks like: not "launch and hope," but systematic work with datasets, end-to-end metrics, and automated eval cycles. This process transforms optimization from a series of intuitive guesses into a managed engineering discipline — with reproducible experiments and a clear history of decisions.
Key Questions Answered
What are the key details on Retrieval Metrics Are Misleading?
Classical search metrics — precision, recall, MRR — show how accurately the system finds the right documents. But they don't answer the main question: did the user receive a useful answer? The Bitrix24 developers encountered a typical production RAG trap: retrieval metrics grew from experiment to experiment, but the actual quality of Martha's answers improved disproportionately — and sometimes didn't improve at all. Retrieval and generation are different links in the same chain. Improving search does not guarantee improving the final answer. The solution is an end-to-end ev
What are the key details on Two Types of Datasets?
The basis of the evaluation system is two datasets with fundamentally different characteristics: Expert dataset — questions and reference answers written manually by specialists who know the product well. Precise and reliable: if the system makes a mistake here, the problem is obvious. The downside — expensive to create, difficult to scale. Synthetic dataset — question-answer pairs automatically generated based on product documentation. Created quickly and in large volumes, but requires filtering: LLM generation inevitably introduces noise and artifacts. Both datasets work
What are the key details on Closed Optimization Loop?
The key practical result of the second part is automation of the experiment cycle. Previously, each change in the retrieval pipeline required manual verification: run eval, collect metrics, compare with the previous version, make a decision. Slow, subjective, and doesn't scale well. The new system closes the loop: change enters the pipeline eval automatically runs on both datasets metrics are compared against baseline regressions are fixed immediately and don't go to production experiment history accumulates in structured form Essentially, it's CI/CD for answer quality. Eac
Build & Ship Production AI Agents Without Boilerplate Code
Start your free 72-hour trial at Hamidun Academy (academy.hamidun.com) — interactive lessons on Claude Code & Cursor, live Tech Radar, and production agent templates.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.