PostgreSQL at OpenAI: How to Scale Databases for ChatGPT
When ChatGPT skyrocketed, the OpenAI team faced a serious challenge: how to ensure stable and fast operation of the database at the foundation of everything – PostgreSQL. This involved supporting hundreds of millions of users and processing millions of requests per second. Solving this task required not just adding more hardware, but a profound rethinking of architecture and the application of a whole range of engineering tricks. PostgreSQL, despite its maturity and reliability, was not originally designed for such extreme loads. Traditional scaling methods, such as vertical scaling (increasing the power of a single server), quickly hit a ceiling. It became clear that a horizontal approach was needed – distributing the load across multiple servers. OpenAI chose the path of replication, creating multiple read-only copies of the database.
AI-processed from OpenAI Blog; edited by Hamidun News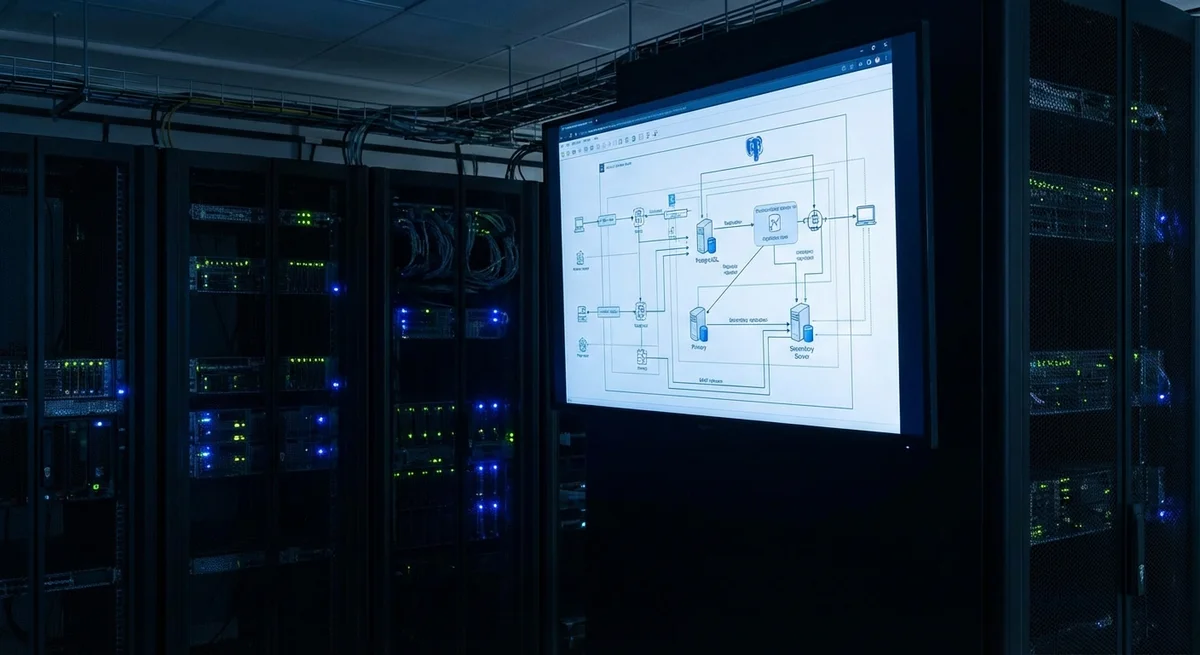
When ChatGPT skyrocketed, the OpenAI team faced a serious challenge: how to ensure stable and fast operation of the database at the foundation of everything – PostgreSQL. This involved supporting hundreds of millions of users and processing millions of requests per second. Solving this task required not just adding more hardware, but a profound rethinking of architecture and the application of a whole range of engineering tricks.
PostgreSQL, despite its maturity and reliability, was not originally designed for such extreme loads. Traditional scaling methods, such as vertical scaling (increasing the power of a single server), quickly hit a ceiling. It became clear that a horizontal approach was needed – distributing the load across multiple servers. OpenAI chose the path of replication, creating multiple read-only copies of the database. This made it possible to significantly reduce the load on the main server and increase overall throughput.
However, replication is only part of the solution. For further optimization, caching was used – storing the most frequently requested data in RAM, which made it possible to avoid accessing the database with each request. In addition, a rate limiting system was implemented, which prevented system overload from sudden traffic spikes. Finally, workload isolation played an important role – dividing different types of requests across different servers to avoid conflicts and ensure priority for the most important operations.
The application of these methods allowed OpenAI not only to handle the current load, but also to create a scalable architecture ready for further growth. This is an important precedent for the entire industry, demonstrating that even mature technologies, such as PostgreSQL, can be successfully used to support the most demanding AI applications. OpenAI's experience shows how important a comprehensive approach is, combining replication, caching, rate limiting, and workload isolation.
The implications of this experience extend far beyond OpenAI. Other companies working with large data and high loads can use these developments to optimize their own systems. In particular, this is relevant for e-commerce platforms, social networks, and other services requiring instant access to large amounts of information. Additionally, this experience can stimulate further development of PostgreSQL and other databases aimed at improving scalability and performance.
In conclusion, OpenAI's success in scaling PostgreSQL is not just a technical achievement, but an important lesson for the entire industry. It shows that the right approach to architecture and optimization can allow even mature technologies to handle the most complex tasks. This opens new opportunities for the development of AI and other areas requiring the processing of large amounts of data.
- Oct 29, 2026TokenRouter speeds up token-level model routing by up to 64x
- Oct 29, 2026Google lets third-party AI agents into Android Studio: Claude, Codex and 40+ more
- Oct 29, 2026Claude Code Edits Video From a Transcript: How the video-use Skill With 30 000 Stars Works
- Oct 29, 2026Anthropic will give companies token reports: customer spending grew 9x in a year
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.