Berkeley PhD students became the AI industry's chief judges: how Arena decides which model is best
UC Berkeley PhD students created Arena — the de facto leading ranking of language models. In seven months, the project grew from a research experiment into a startup whose evaluations influence funding rounds and marketing campaigns of the largest AI companies.
AI-processed from TechCrunch; edited by Hamidun News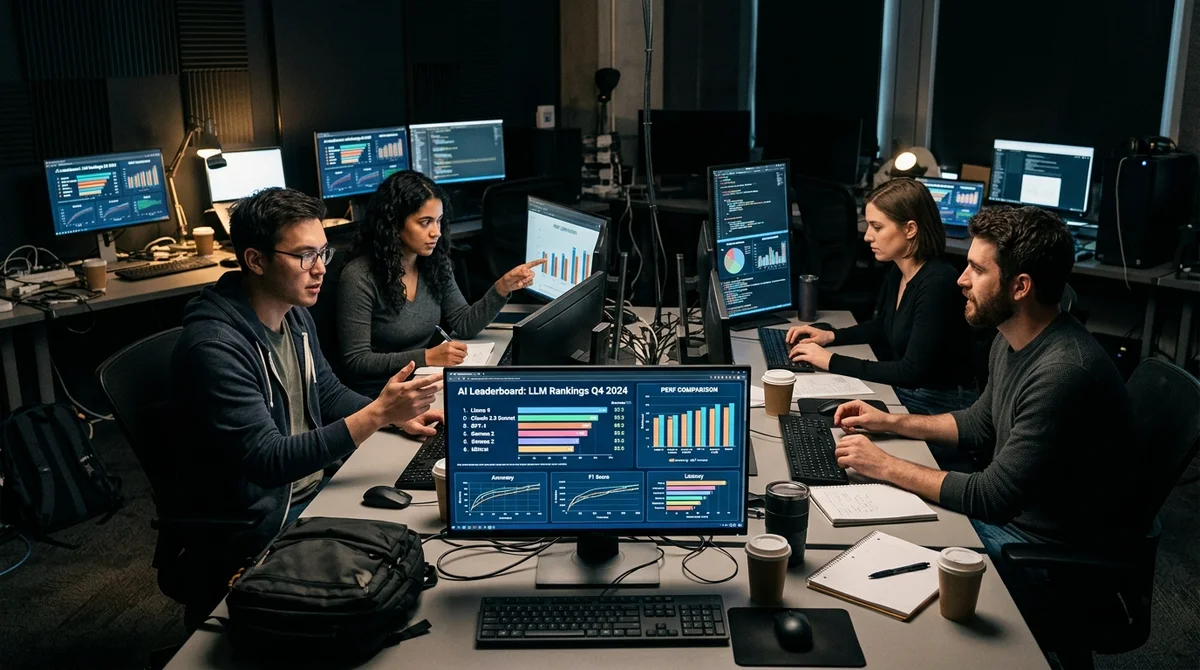
While AI companies compete for the title of best model, the authority to render a verdict has fallen to a group of graduate students from the University of California, Berkeley. Arena, formerly known as LM Arena, has become the leading public leaderboard for frontier models. Its rankings are cited in press releases, considered by venture investors, and used by development teams when selecting a base model.
Over just seven months, the project transformed from an academic experiment into a full-fledged startup with real influence on the industry. Arena's operating principle is based on crowdsourcing: users compare answers from two anonymous models and vote for the better one. The system accumulates millions of such comparisons and translates them into a ranking using the Elo method—the same mathematics that rates chess players.
Model anonymity eliminates brand bias: users don't know whose answer they're reading until they vote. The infrastructure that grew from a university project now influences the biggest market players. When OpenAI, Google, or Anthropic release a new model, one of the first indicators of success becomes its position in Arena.
Venture funds monitor the ranking when making investment decisions. Marketing teams build PR campaigns around a line in the leaderboard. Yet the system has obvious limitations.
An internet audience votes, not a representative sample of professionals. The tasks users pose to the models don't always reflect real production scenarios. Finally, active Arena users are typically technically savvy enthusiasts, not the average corporate client.
Nevertheless, Arena has filled a gap that academic benchmarks couldn't close. Standard tests like MMLU or HumanEval measure narrow capabilities in controlled conditions. Arena measures something harder to formalize: whether people like this answer.
This feeling ultimately determines which model a user will choose. Arena's story is an instructive example of how the academic community can set standards in a fast-developing industry where corporations lack both the time and incentive to create neutral evaluation infrastructure. The question is whether this neutrality will be preserved as the startup grows and attracts outside funding.
- Oct 28, 2026Keystone removes the model name from code: open-source LLM gateway adds 0.64 ms
- Oct 28, 2026Wired Tested 6 AI Agents in a Day: Dots Leads, Gemini Spark Fails at Lunch
- Oct 28, 2026Anthropic Turns Claude Code Into a Platform: Claude Mods Flip the Agent Harness
- Oct 28, 2026Liquid AI releases LFM2.5-24B-A2B: an agent model with 2B active parameters
Ship AI Faster with Founders, Engineers & Weekly Architecture Reviews
Inside Vibe Club (hamidun.com/club) — weekly live masterminds with Zhemal Khamidun, Tech Radar, full LMS access, and 370+ production Claude Code skills.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.