Amazon SageMaker and DVC: end-to-end traceability of ML models from data to prediction
AWS published a guide to end-to-end traceability for ML models using DVC, Amazon SageMaker AI, and MLflow Apps. It covers two patterns: lineage at the dataset level and at the individual-record level. Both are deployed in your AWS account through ready-made notebooks.
AI-processed from AWS Machine Learning Blog; edited by Hamidun News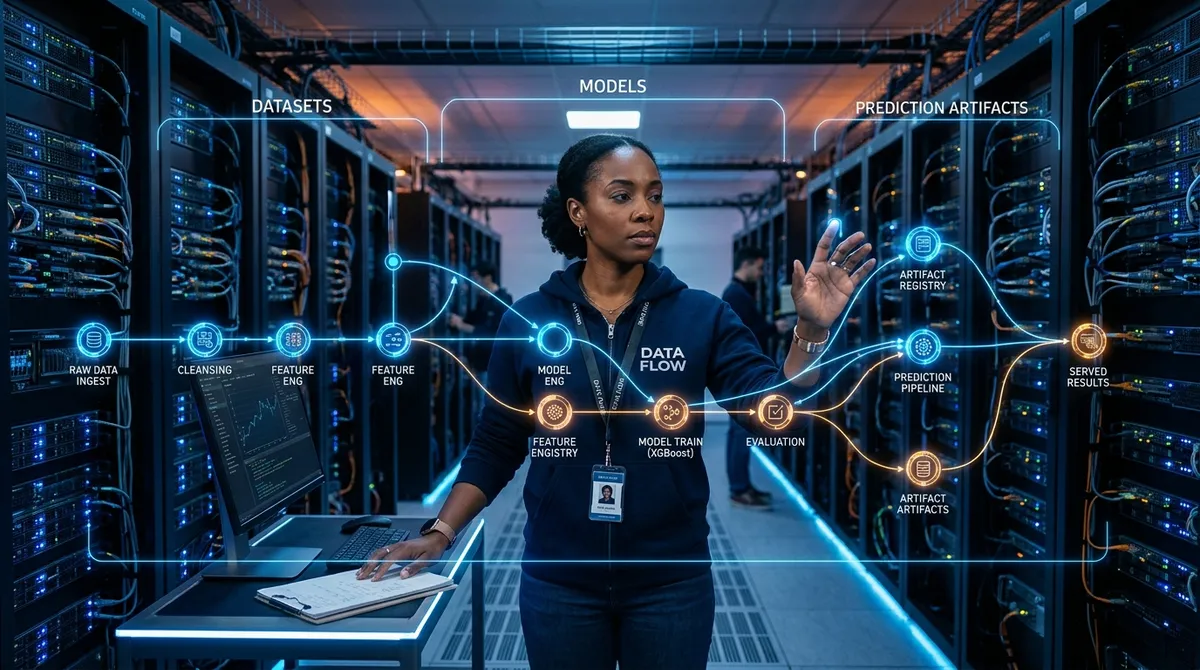
AWS Machine Learning Blog published a detailed guide on building end-to-end ML model tracking — from raw data to final prediction — using three tools: DVC, Amazon SageMaker AI and Amazon SageMaker AI MLflow Apps. The problem that the material addresses is well-known to teams working in production: it's unclear which exact data was used to train a specific model, what transformations were applied to it, and how an individual record influenced the prediction. This is critical during audits, debugging data drift, and compliance with regulatory requirements.
DVC (Data Version Control) is an open-source tool that adds versioning of large files and datasets to Git. In combination with SageMaker, it allows you to capture the exact snapshot of data used in each training run. SageMaker MLflow Apps, in turn, stores metrics, parameters, and experiment artifacts — a standard MLflow server managed by AWS without the need to deploy infrastructure manually.
The authors describe two concrete patterns. The first is dataset-level lineage: the dataset version is recorded (via DVC tag), processing pipeline parameters, and a link to the trained model in MLflow. The second is record-level lineage: each specific record from the training set is tied to the model, which allows answering the question "which exactly examples shaped this prediction".
Both patterns are implemented as Jupyter notebooks ready to run in your AWS account. The architecture looks as follows: data is stored in S3 and versioned by DVC, experiment metadata (parameters, metrics, artifacts) — in MLflow App, and the connection between data version and model version is provided through custom tags and DVC artifacts registered in MLflow. The practical value of the approach is in reproducibility.
If in six months it turns out that the model behaves unexpectedly on a certain cohort of users, engineers will be able to precisely recover which dataset it was trained on, which records it included, and with what hyperparameters the training was launched. The material is aimed at ML engineers and MLOps teams already working in the AWS ecosystem. Ready-made notebooks significantly lower the entry barrier: there is no need to design the integration from scratch — it is enough to adapt the examples to your dataset and processing pipeline.
For companies where auditability of ML systems is important — especially in the financial sector, medicine, and government projects — such an approach becomes a de facto standard. AWS is consistently building a toolkit in which lineage stops being an optional "best practice" and becomes an embedded property of the pipeline.
- Oct 28, 2026Keystone removes the model name from code: open-source LLM gateway adds 0.64 ms
- Oct 28, 2026Wired Tested 6 AI Agents in a Day: Dots Leads, Gemini Spark Fails at Lunch
- Oct 28, 2026Bayer Launches Multi-Agent Engine on AgentCore: 80% of Questions Handled Without Engineers
- Oct 28, 2026Anthropic files S-1 for IPO at $2 trillion valuation: 85% margin, profitable Q2
Ship AI Faster with Founders, Engineers & Weekly Architecture Reviews
Inside Vibe Club (hamidun.com/club) — weekly live masterminds with Zhemal Khamidun, Tech Radar, full LMS access, and 370+ production Claude Code skills.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.