How YOLO and OpenCV Learned to Parse Shipping Waybills — and Why That Is Not Enough
OCR reads everything, but it does not understand document structure, and that is the main problem when automating shipping waybill parsing. This piece examines how YOLO, OpenCV and Hugging Face perform on real tasks: where their limits lie, how to extract meaning from raw detector outputs, and how to build logic around what has been recognized, from simple inference to video analytics. The verdict is pragmatic: the tools work, but they do not solve the task of understanding a document automatically.
AI-processed from Habr AI; edited by Hamidun News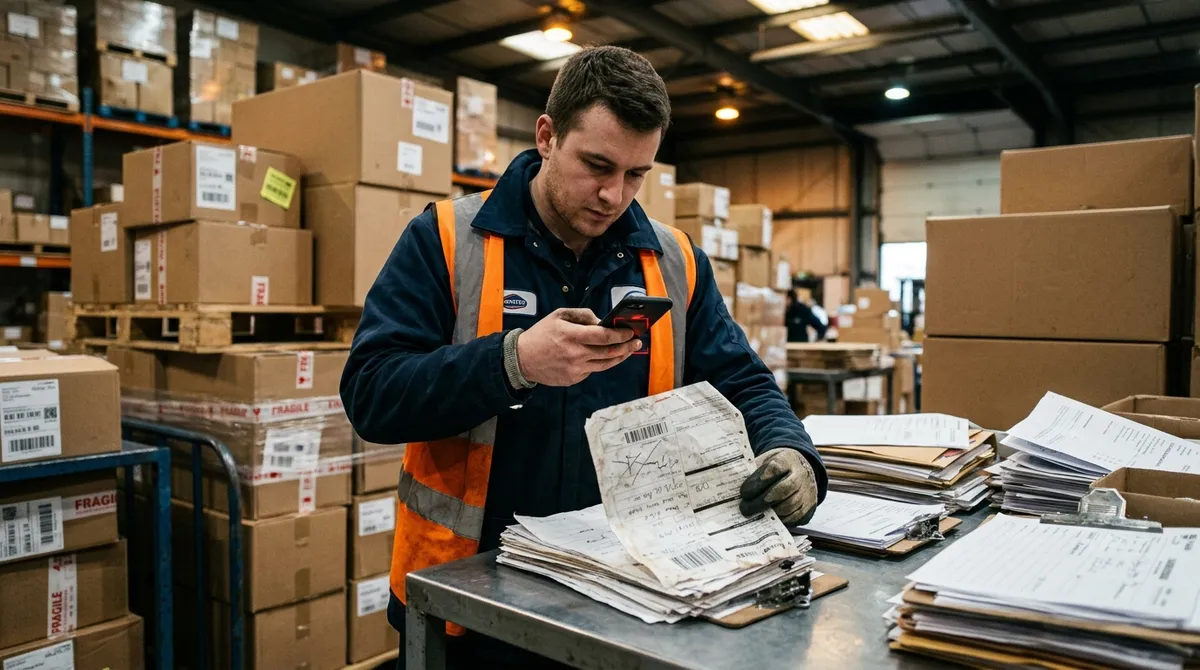
When OCR calls a shipping waybill "read," it means only one thing: the system has extracted characters. Figuring out which part is the sender, which is the cargo and which is the total amount is an entirely different task, and OCR does not solve it by default. Modern computer vision libraries such as YOLO, OpenCV and models from Hugging Face can recognize objects, text blocks and structures in just a few lines of code. That is convenient for prototyping, but serious limitations hide behind the simplicity. Out-of-the-box models are trained on general datasets. They do not know what your specific waybill form looks like, which fields are mandatory and which are optional notes.
The article walks through a real case: building a system that automatically extracts data from shipping waybills. Documents arrive in different formats: low-resolution scans, phone photos, PDFs from various accounting systems. In this scenario OCR is only the first step. Then the real engineering begins.
The first limitation any team faces is input quality. YOLO detects objects well on clean images, but shipping waybills are rarely perfect: crumpled paper, skewed shooting angles, poor lighting, overlapping stamps and seals. OpenCV helps with preprocessing, such as perspective correction, noise filtering and contrast normalization, but each of these steps needs manual tuning for a specific document type. There are no universal parameter values.
The second limitation is semantics. A detector can draw a rectangle around the number "15 000," but it does not know whether that is a unit price, a total amount or a waybill number. This requires extra logic: an understanding of table structure, row order and the relative position of fields. The authors describe an approach that uses NLP models from Hugging Face to classify detected text blocks; the model learns to tell field types apart from the context of neighboring elements.
The third problem is performance in real-world conditions. When the task grows from one-off parsing into a stream, with dozens of waybills per minute or a video analytics scenario where frames must be processed in real time, the architecture requirements change radically. The authors describe optimizing the inference pipeline: request batching, model quantization, choosing between CPU and GPU depending on workload volume and acceptable latency, and asynchronous processing as a way to squeeze the most out of available hardware.
A separate section covers post-processing of results, meaning what happens after the detector returns coordinates and text blocks. This stage needs validation rules (a correct INN taxpayer number, the right date format, matching totals), conflict-resolution logic (when two fields claim the same value) and error-handling mechanisms. Without this layer, the system will read but not understand.
The practical conclusion is simple: the tools exist and they work, but they do not solve the task of "understanding a document" automatically. YOLO is a detector, not an interpreter. OpenCV processes pixels, not meaning. Hugging Face offers a rich choice of pretrained models, but fine-tuning for a specific domain is still necessary. A real document parsing system is a pipeline of several models, post-processing rules and validation, where each layer adds semantics to what the previous one only saw.
The limit of off-the-shelf solutions lies where recognition ends and understanding begins. The more specific the domain (logistics, medicine, legal documents), the further that limit moves from "just grab a model" and the closer it gets to custom development from scratch.
- Nov 2, 2026Karpathy builds a YouTube clone with 6454 videos from Hacker News recommendations in two hours
- Nov 2, 2026Karpathy used Claude to build HackerTube from 6,454 videos recommended on Hacker News
- Nov 2, 2026Microsoft releases 4B model Mage-VL-Cowork, which solves 66.0% of OSWorld-Verified tasks
- Nov 1, 2026Local models lose to Opus and Codex: 0.21 on a MacBook versus 1.00 for Codex
Ship AI Faster with Founders, Engineers & Weekly Architecture Reviews
Inside Vibe Club (hamidun.com/club) — weekly live masterminds with Zhemal Khamidun, Tech Radar, full LMS access, and 370+ production Claude Code skills.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.