Wildberries & Russ outlines the data maturity level AI agents need to be accurate
Wildberries & Russ has proposed a maturity model for data documentation, running from Rare to Well-Done, and shows why AI agents start to hallucinate even on simple SQL tasks when metadata is poor. At the basic level, a dataset needs an owner, a physical model and confidentiality tags. At the middle level, it needs a glossary and a logical layer. At the target level, it needs a full semantic layer to support text-to-SQL and accurate business metrics.
AI-processed from Habr AI; edited by Hamidun News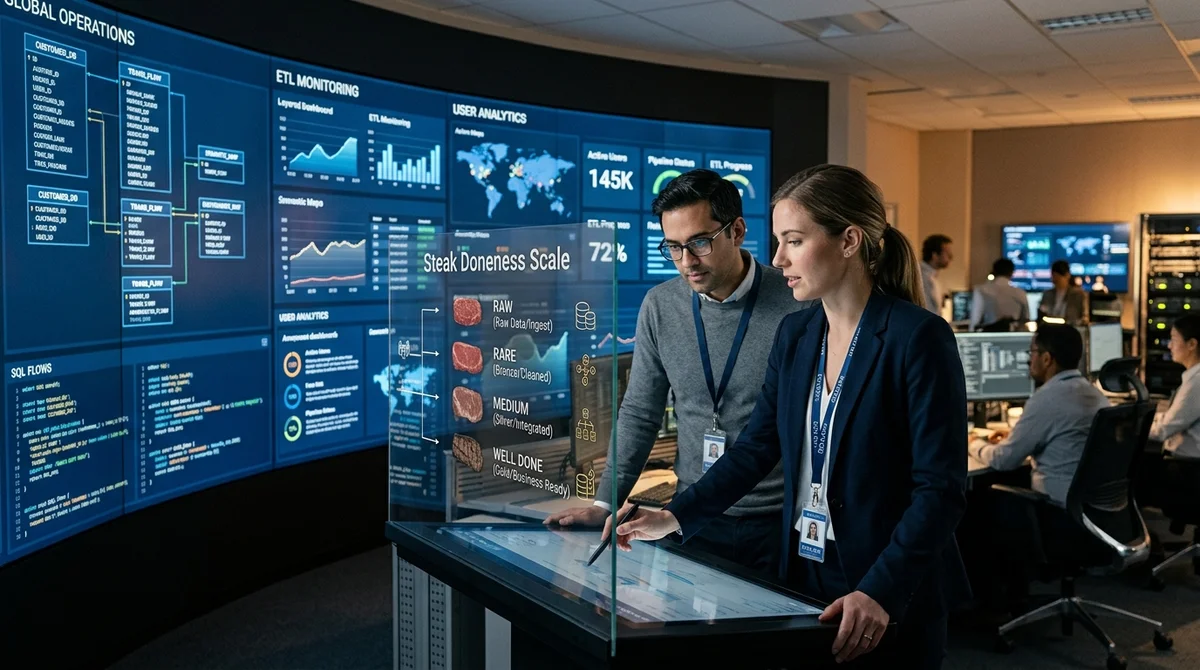
Wildberries & Russ suggests judging the quality of data documentation as pragmatically as the doneness of a steak: from Rare to Well-Done. The idea is simple: the better a company describes its tables, fields, business terms and metrics, the less its AI agents hallucinate and the closer they get to real business insight rather than plausible but useless answers.
The company argues that the main problem with big data today is not a shortage of models but weak upkeep of the data itself. In a large organization, new tables appear faster than teams can document them by hand. As a result, analysts waste time hunting for the right sources, metrics drift apart between reports, and access to unlabeled datasets becomes a security risk. This is especially acute where personal data and strict access-control requirements are involved. A manual approach simply stops scaling in such an environment.
The first maturity level, Rare, is considered the minimum sufficient for working with data safely. At this level, every dataset must have an owner, a physical model and confidentiality labeling. The physical model can be extracted automatically from system tables and data catalogs, and if field descriptions are empty, AI can try to reconstruct them from naming conventions and corporate knowledge bases. Automation works less well for owners: a model can suggest a candidate, but responsibility is still assigned manually. Labeling sensitive data, however, looks like one of the first practical tasks for LLMs: a model can analyze the names of tables, columns and business terms and assign security tags before any deep scan of the contents.
At the Medium level, the emphasis shifts from technical structure to business meaning. This is where a glossary and a logical layer appear, translating the language of tables and columns into entities and attributes the business understands. Such a layer hides service prefixes, complex joins and storage details, and data stewards can use AI as a copilot to map fields to existing terms and to find gaps in descriptions.
If an agent is connected to the metadata catalog via MCP, it can pull the needed schemas on request, match them against the glossary and speed up work that used to take hours. Wildberries & Russ also proposes extracting relationships not only from the structure of the warehouse but from SQL query logs: they show which tables analysts join most often, which filters they use and how data is actually consumed.
The highest level, Well-Done, is needed not merely to navigate data but for text-to-SQL and agentic systems to work properly. Here a semantic layer is built on top of the physical and logical description: facts, metrics, dimensions, relationships, filters and verified natural-language queries with ready SQL answers. This layer explains to the model what the business means by an "active customer", "gross revenue" or another metric, rather than forcing it to guess the meaning from field names.
The article gives a telling example. If you ask an AI how many active customers there were in March, a model without semantics may simply count rows with the status active, even though under company rules an active customer is one who has placed at least one order above a set threshold. According to the author, this is where open standards such as OSI become critically important, because they let teams describe the meaning of data in a portable format compatible with modern semantic-layer tools.
The practical effect is also noted: Snowflake's materials for Cortex Analyst mention an accuracy gain of roughly 20 percent when working through correctly described semantics, and the target bar for real-world scenarios is more than 90 percent SQL accuracy.
What this means in practice: the market is gradually moving away from the idea that it is enough to simply connect an LLM to a database and wait for magic. The Wildberries & Russ approach shows a more sober path: first put owners, structure and data classification in order, then build a logical dictionary, and only after that build a semantic layer for agents. For companies that want to bring AI assistants into analytics, this is an unpleasant but useful truth: the quality of a model's answer now depends not only on the model itself but on the maturity of data documentation inside the business.
- Nov 2, 2026Karpathy builds a YouTube clone with 6454 videos from Hacker News recommendations in two hours
- Nov 2, 2026Karpathy used Claude to build HackerTube from 6,454 videos recommended on Hacker News
- Nov 2, 2026Arca gives AI agents finance tasks lasting up to 10 days, but leaves the trades to humans
- Nov 2, 2026DeepSeek open-sources Super-agent prototype: p95 task completion time of 15.7 minutes vs. 29.5
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.