Yandex Cloud explains why the frontend leads AI integration in DataLens at launch
Yandex Cloud has described how DataLens handed the first layer of AI integration to a frontend team. Instead of depending entirely on the backend, it uses a BFF that handles the model, the context and streaming. The key idea is simple: if data and state live next to the interface, launching Neuroanalyst from there is faster. This approach lets a team test a product hypothesis without a big server-side overhaul.
AI-processed from Habr AI; edited by Hamidun News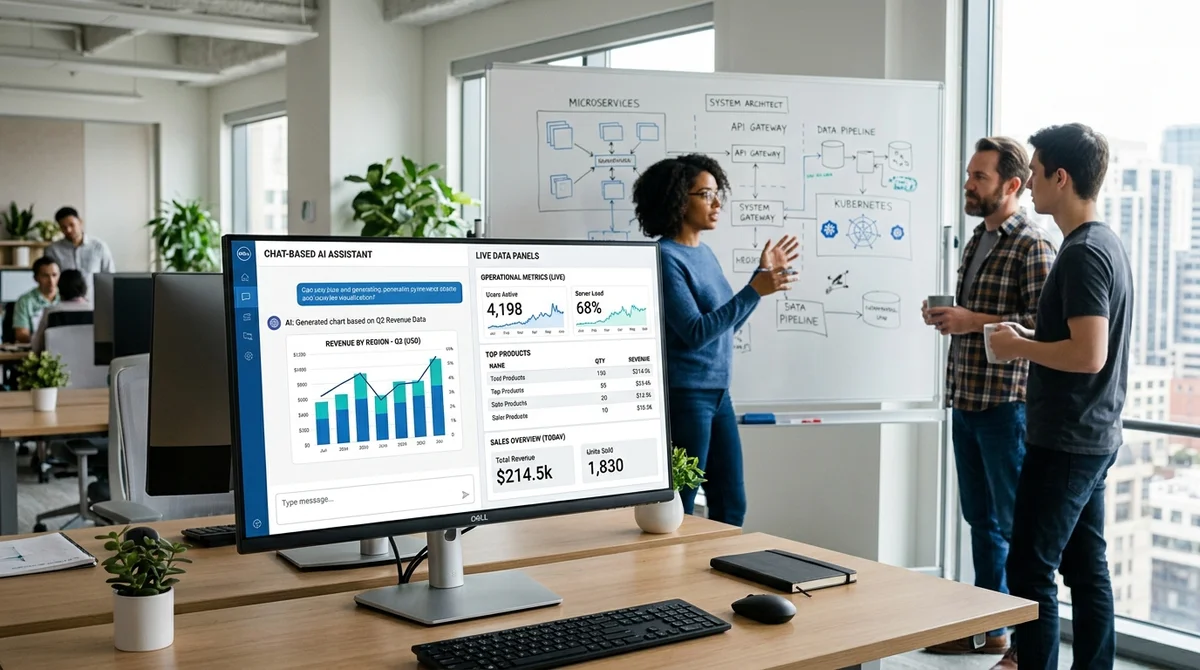
Yandex Cloud suggests treating the integration of neural networks into a product as more than a backend-only task. In DataLens, a frontend team built the first working layer of Neuroanalyst: it put together the chat interface, a BFF layer and the logic for talking to the model, without waiting for a major server-side rework. The idea is that for an early launch of AI features, a perfect architecture built to last years matters less than getting to market quickly with a clear division of responsibility.
The case in question is DataLens, Yandex Cloud's BI system for visualizing large datasets. The service now includes Neuroanalyst, an assistant that helps build charts, write formulas and solve analytical tasks in a dialogue. Instead of the classic setup in which the backend fully owns the LLM integration, the team proposed a different order: a BFF layer sits between the client and the model, and the frontend is responsible for it. Such a layer can run on Node.js, Bun or another familiar stack and serve as a separate server geared to the needs of the interface.
The author illustrates the approach with a demo project: a monorepo with Express and React, in which a BI dashboard runs next to a chat assistant. In this setup the existing backend does not need to be rewritten urgently. The BFF stores the model access keys, handles rate limiting, CORS, logging and monitoring, and manages response streaming.
For frontend developers this is not foreign territory: in many product teams they have long worked as full-stack engineers, maintaining server code, CI/CD and the infrastructure around the client application. So the first stage of integration can be done closer to the interface, where the effect on users is most quickly visible. If the hypothesis fails, the cost of the mistake is lower than with a deep rework of the main backend.
The authors of the approach identify four basic components of such an integration. First, a UI kit for the chat interface and related elements: input fields, cards, action lists, message streaming. Second, an SDK for working with the model through an API; what matters here is not the specific provider but compatibility, because many services replicate the OpenAI API format.
Third, tooling, meaning function calling and the model's access to application functions, for example fetching data for a chart or selecting the top 5 products. Fourth, context: dialogue history, application state, user code, computation results and errors that the model needs to give a meaningful answer. These four layers are, at a basic level, enough to launch a working AI feature in an interface.
The author sees context as the main argument for the frontend. An LLM has no memory of its own, so every request must pass along the conversation history and everything needed for the answer. In BI products a significant share of the data lives on the client: open tabs, current dashboard settings, query fragments, error messages, intermediate results and sometimes pieces of user code.
Sending all of this to the backend for every model response is expensive and not always sensible. Meanwhile, although models' context windows keep growing, they are usually still limited to tens or hundreds of thousands of tokens, and sometimes a million, and they cannot be used without selection. Models also still handle exact calculations poorly, so they need not just a lot of data but well-packaged data and access to tools that compute and retrieve the necessary facts.
For the market this is an important signal: integrating AI into a product is ceasing to be a backend monopoly and becoming a joint engineering task, in which the frontend can take on the starting stage and bring an idea to users faster. As load grows, background operations appear and ties to internal systems deepen, the backend's role will, of course, grow again. But at an early stage, this BFF approach lets teams test scenarios faster, gather product insights and avoid delaying the launch over a large architectural overhaul. For teams still looking for a place for their first LLM feature, it is a practical way to start without excess organizational weight.
- Nov 2, 2026Arca gives AI agents finance tasks lasting up to 10 days, but leaves the trades to humans
- Nov 2, 2026Meta's Muse assistant keeps dossiers on loved ones and gets root on Ubuntu by default
- Nov 1, 2026Local models lose to Opus and Codex: 0.21 on a MacBook versus 1.00 for Codex
- Nov 1, 2026Kimi scores 96.2% on a 1C database analytics test and emerges as a fallback if Claude access is blocked
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.