MIT develops a method for detecting discrimination in AI decision-support systems
MIT researchers have developed a framework for testing the ethics of autonomous AI systems. The tool pinpoints the situations in which AI decision-support systems treat people unfairly. The method covers healthcare, lending and criminal justice, wherever algorithms make decisions that affect real people. The framework lets developers and regulators detect bias before systems are deployed.
AI-processed from MIT News; edited by Hamidun News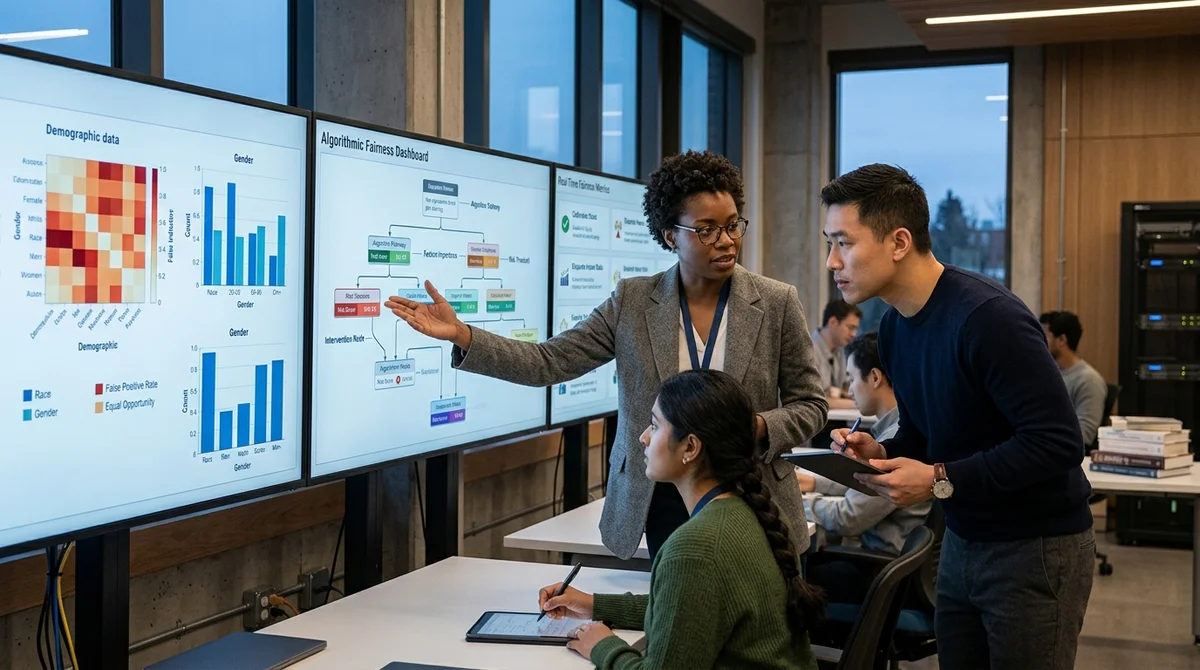
Researchers at the Massachusetts Institute of Technology have developed a testing framework that systematically identifies situations in which autonomous AI systems make unfair decisions about specific people and entire communities. The work closes one of the key gaps in the toolkit for evaluating AI ethics: the lack of a methodology that can find discrimination not only in statistics but in concrete scenarios.
Where bias does harm
Decision-support systems, meaning algorithms that help make decisions in healthcare, lending, education, hiring and criminal justice, are becoming ever more embedded in everyday processes. These are the areas where algorithmic bias causes the most tangible real-world harm. A person is denied a mortgage, their résumé is filtered out before the interview stage, or they receive a harsher sentence, all without a clear explanation and often without any way to appeal the decision.
Limits of existing methods
Existing approaches to auditing AI systems typically measure demographic disparities in aggregated results. This kind of analysis can detect large systematic skews, but it misses subtle, context-dependent cases of discrimination. A system can show statistical parity overall while systematically giving unfavorable recommendations to members of certain groups under specific case circumstances. Classic fairness metrics simply do not see such localized violations.
MIT's scenario-based approach
The MIT framework tackles this problem with a scenario-based approach. The tool automatically generates test sets: situations in which specific parameters vary, such as the applicant's demographic characteristics, their history of requests, the wording of questions and the surrounding context. The system then analyzes how the AI model reacts to these variations and identifies patterns that point to unfair treatment.
The key difference is that the framework looks not only for gaps between demographic groups at the statistical level, but also for the specific situational triggers that provoke biased outputs. In tests on several real-world AI systems, the researchers confirmed that bias is often concentrated in narrow, specific scenarios that a standard audit simply misses. This means that developers and regulators who rely only on aggregated metrics may get a false sense of security while real discrimination continues at the level of individual cases.
Practical use and regulation
The MIT team deliberately designed the tool to be practical, not just a research artifact. The methodology is compatible with existing responsible-AI standards, notably the NIST AI Risk Management Framework, and could potentially be built into mandatory checks of systems before they reach the market. The authors describe possible use cases ranging from internal reviews at developer companies to independent audits by regulators.
The study arrives amid growing regulatory pressure on the AI industry. In Europe, the AI Act requires providers of high-risk systems to undergo risk assessment and maintain documentation. In the US, several states have already introduced algorithmic accountability legislation, and federal agencies are increasingly looking at algorithmic discrimination.
In this context, standardized testing tools are exactly what regulators currently lack.
Conclusion
MIT's work draws a simple but important conclusion: AI ethics is not only a matter of intentions and declarations, but also of verification. Without tools able to detect unfairness in specific situations, even the most conscientious developers risk shipping a system with unnoticed violations. The new framework offers a concrete step toward making promises of fair AI verifiable in practice.
- Nov 2, 2026Karpathy builds a YouTube clone with 6454 videos from Hacker News recommendations in two hours
- Nov 2, 2026Karpathy used Claude to build HackerTube from 6,454 videos recommended on Hacker News
- Nov 2, 2026Arca gives AI agents finance tasks lasting up to 10 days, but leaves the trades to humans
- Nov 2, 2026DeepSeek open-sources Super-agent prototype: p95 task completion time of 15.7 minutes vs. 29.5
Key Questions Answered
Where bias does harm?
Decision-support systems, meaning algorithms that help make decisions in healthcare, lending, education, hiring and criminal justice, are becoming ever more embedded in everyday processes. These are the areas where algorithmic bias causes the most tangible real-world harm. A person is denied a mortgage, their résumé is filtered out before the interview stage, or they receive a harsher sentence, all without a clear explanation and often without any way to appeal the decision.
What are the key details on Limits of existing methods?
Existing approaches to auditing AI systems typically measure demographic disparities in aggregated results. This kind of analysis can detect large systematic skews, but it misses subtle, context-dependent cases of discrimination. A system can show statistical parity overall while systematically giving unfavorable recommendations to members of certain groups under specific case circumstances. Classic fairness metrics simply do not see such localized violations.
What are the key details on MIT's scenario-based approach?
The MIT framework tackles this problem with a scenario-based approach. The tool automatically generates test sets: situations in which specific parameters vary, such as the applicant's demographic characteristics, their history of requests, the wording of questions and the surrounding context. The system then analyzes how the AI model reacts to these variations and identifies patterns that point to unfair treatment. The key difference is that the framework looks not only for gaps between demographic groups at the statistical level, but also for the specific situational trig
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.