VK shows DataCopilot — multi-agent system for corporate data and documentation
VK unveiled DataCopilot — an internal AI assistant for corporate data repositories and documentation. The system emerged from an audit of real requests to Data Office and data platform engineers: it helps search data marts, explain where data is stored, suggest access permissions, and even prepare ETL scripts. Instead of a single RAG pipeline, the team chose a multi-agent architecture for different task types.
AI-processed from Habr AI; edited by Hamidun News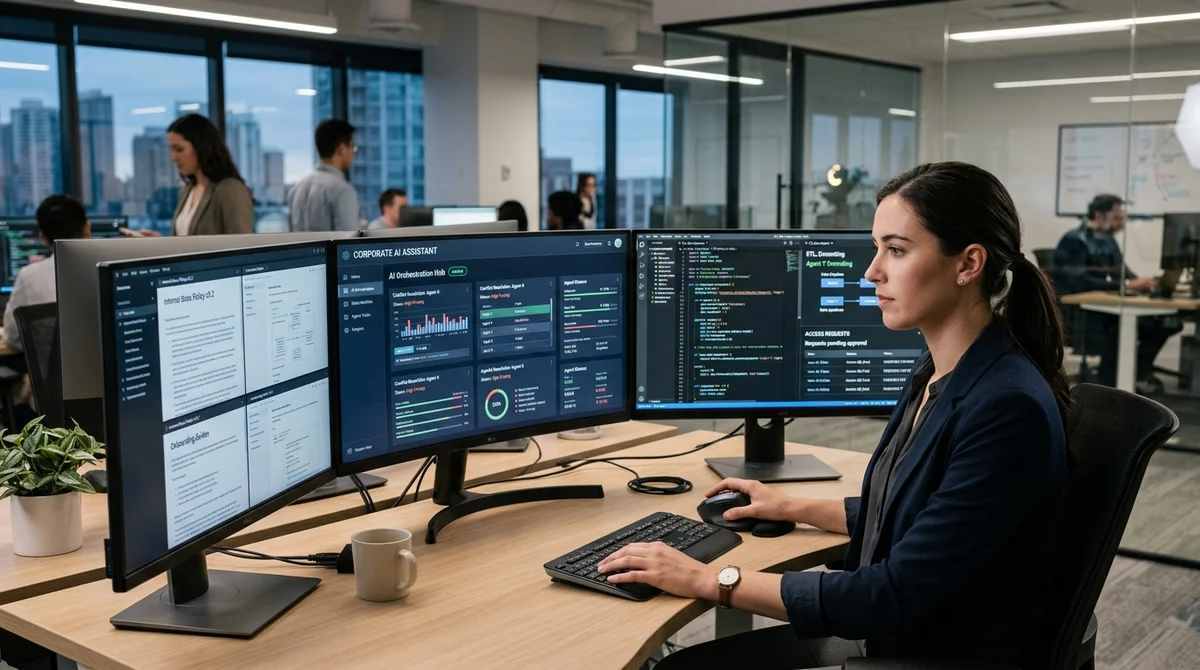
VK showed DataCopilot — a multi-agent system for corporate data and documentation
VK presented DataCopilot — an internal AI assistant for working with a corporate data repository and specialized documentation. The project grew not out of a trend around LLMs, but from analyzing real requests from analysts, managers, and engineers who spend time every day on repetitive questions.
How they started
The team didn't begin by choosing a model or designing another RAG schema. First, VK looked at the routine around Data Office and the data platform: what questions come into support, what do employees ask most in chats, where do people lose time searching for the right dashboard, field description, or approval process. This audit provided a clear list of tasks that could be automated without rebuilding the entire DWH and without trying to create "universal intelligence" for every case at once.
From this list, they formed the image of the future assistant. It should understand the catalog of dashboards, explain what and where is stored, provide hints about corporate documentation, help with access, and generate working templates for ETL. That is, not a chatbot "for the sake of a chat," but an interface to the company's data and internal knowledge.
For analysts and managers, this saves time; for engineers, it reduces the flow of identical requests.
Why not RAG
For some requests, classical RAG indeed works: a user asks a question, the system finds relevant documents and assembles an answer based on them. But in a corporate environment, this quickly becomes insufficient. One question may require moving between the dashboard catalog, descriptions of specific tables, access instructions, and a script template.
If all of this is handed to a single chain without specialization, the quality of the answer begins to fluctuate, and extra context only gets in the way. That's why VK bets on a multi-agent architecture — essentially, on a swarm of specialized assistants. One agent can be responsible for searching and interpreting documentation, another for navigating the repository, a third for generating code, a fourth for access provisioning scenarios.
Above them is a coordinator that understands the type of request, chooses the route, and assembles the final answer. This approach aligns better with the actual structure of corporate data, where sources, rules, and actions differ significantly from each other.
What the system can do
Based on the project description, DataCopilot is built as a practical work tool, not as a demonstration of model capabilities. It covers the points where an employee normally has to switch between support chats, the data catalog, internal instructions, and their own drafts. As a result, the user gets either a short answer with the necessary context or a semi-finished artifact that can be quickly adapted to the task.
- Helps find the right dashboard and understand what data it contains
- Explains exactly where information is stored and how it relates to other entities
- Advises how to submit an access request without going to support
- Answers specific questions about internal documentation and DWH operating rules
- Writes scripts that can be taken into ETL processes and refined for your pipeline
An important point here is that the system works at the intersection of knowledge and action. It not only retells documents but also helps take the next step: prepare a request, draft a script, shorten the path to the needed table. This is usually what distinguishes a useful corporate AI from just another "smart search." At the same time, responsibility for the final application of results remains with the human: especially when it comes to access, data migrations, and code for production ETL processes.
What this means
The DataCopilot story shows where corporate AI is really moving: not toward one all-knowing chatbot, but toward a set of narrow agents around a specific work workflow. For teams that have a DWH, a dashboard catalog, regulations, and a stream of repetitive questions, such an approach can deliver much more value than abstract RAG on top of all documents at once.
- Oct 30, 2026Google's Gemini 4 Carbon Scores 88.2% on Vulnerability-Finding Benchmark, Access Remains Restricted
- Oct 29, 2026Google lets third-party AI agents into Android Studio: Claude, Codex and 40+ more
- Oct 29, 2026A Swarm of AI Agents Builds the Game Spawn, and Tokens Cost $3 Million a Month
- Oct 29, 2026Mistral Releases Large 4 Weights: Open 1T-Parameter Model for Coding
Key Questions Answered
How they started?
The team didn't begin by choosing a model or designing another RAG schema. First, VK looked at the routine around Data Office and the data platform: what questions come into support, what do employees ask most in chats, where do people lose time searching for the right dashboard, field description, or approval process. This audit provided a clear list of tasks that could be automated without rebuilding the entire DWH and without trying to create "universal intelligence" for every case at once. From this list, they formed the image of the future assistant. It should understa
Why not RAG?
For some requests, classical RAG indeed works: a user asks a question, the system finds relevant documents and assembles an answer based on them. But in a corporate environment, this quickly becomes insufficient. One question may require moving between the dashboard catalog, descriptions of specific tables, access instructions, and a script template. If all of this is handed to a single chain without specialization, the quality of the answer begins to fluctuate, and extra context only gets in the way. That's why VK bets on a multi-agent architecture — essentially, on a swar
What the system can do?
Based on the project description, DataCopilot is built as a practical work tool, not as a demonstration of model capabilities. It covers the points where an employee normally has to switch between support chats, the data catalog, internal instructions, and their own drafts. As a result, the user gets either a short answer with the necessary context or a semi-finished artifact that can be quickly adapted to the task. Helps find the right dashboard and understand what data it contains Explains exactly where information is stored and how it relates to other entities Advises ho
Build & Ship Production AI Agents Without Boilerplate Code
Start your free 72-hour trial at Hamidun Academy (academy.hamidun.com) — interactive lessons on Claude Code & Cursor, live Tech Radar, and production agent templates.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.