Yandex Praktikum explains how CNNs see images, and why parameter count isn't everything
Yandex Praktikum has published a clear explainer on Habr AI about convolutional neural networks. It covers how filters detect features in an image and why a higher parameter count does not guarantee a better result. The piece targets newcomers to computer vision and developers who have used CNNs as a black box and want to understand how computer vision actually works.
AI-processed from Habr AI; edited by Hamidun News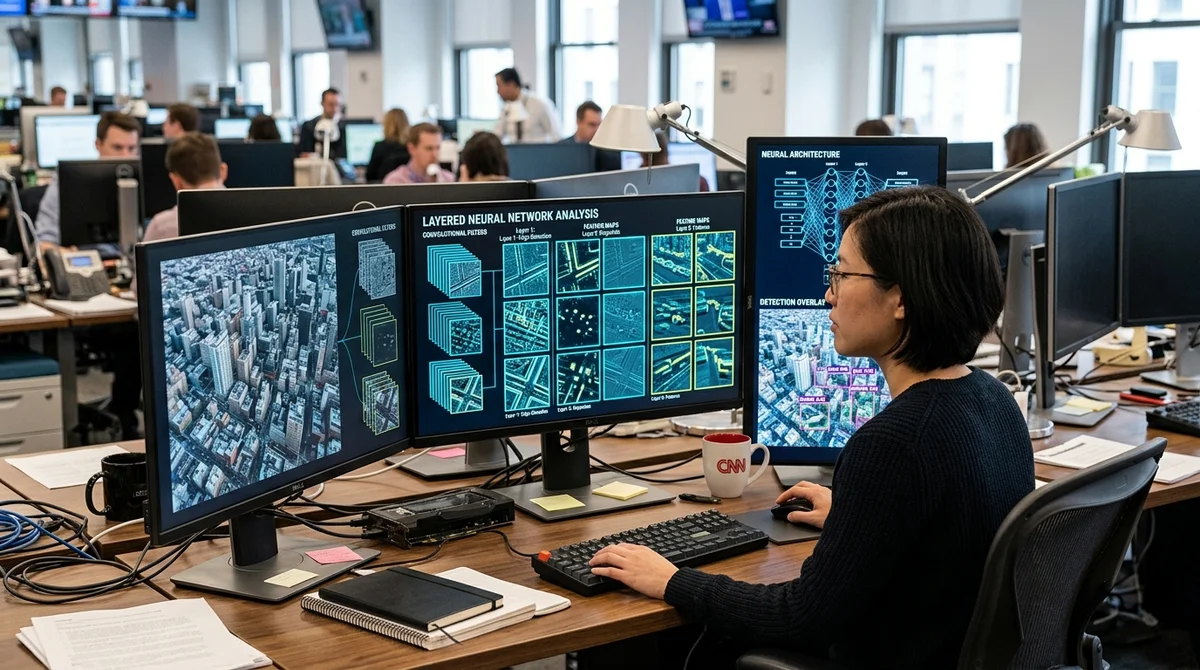
Yandex Praktikum has published a detailed explainer on Habr AI about how convolutional neural networks process images and why model quality cannot be reduced to parameter count. The piece is written as an entry point to computer vision for readers who have used CNNs as a ready-made tool but have never looked at what happens inside.
How CNNs see
A convolutional network treats a picture not as a single whole object but as a grid of pixels that small filters slide across. Each filter looks for a local pattern: an edge, a corner, a repeating texture or a simple contrast. Because the same set of weights is reused across different parts of the image, the network learns to find familiar features regardless of where they sit in the frame. This is what makes CNNs practical for vision tasks: they extract structure rather than simply memorizing the whole picture.
The features are then assembled into a hierarchy. Lower layers usually respond to simple elements such as lines and edges, middle layers to shapes and textures, and upper layers to more complex combinations tied to objects. Stride, pooling and network depth play an important role: they shrink the representation, widen the model's field of view and help preserve meaningful information. As a result, a CNN's final answer comes not from a single layer but from the gradual accumulation of context.
Why few parameters can be enough
One of the article's central points is that a bigger model does not automatically become a better one. Parameter count shows the size of a network, but says almost nothing about how well the architecture was chosen, how carefully the data was prepared, or whether the model suits a specific task. For classifying defects on a production line, for medical images or for cameras in a mobile device, the winner is not the heaviest network but the one that delivers the required accuracy at a reasonable cost in memory, speed and robustness.
"Many parameters" does not always mean "the best neural network."
In practice, an engineer has to look wider: how the network behaves on new data, how easily it overfits, how many resources it needs for training and inference, and whether it can be deployed on an edge device or built into a product without extra latency. So the article shifts the CNN discussion from an abstract race for size to engineering trade-offs. That is a useful emphasis in a market where model power is often sold as the only measure of quality.
Who this explainer is for
In format, this is neither a scientific publication nor an ad for a course, but a practical introduction to the mechanics of computer vision. The author explicitly addresses two audiences: those just entering CV, and those who have already used off-the-shelf CNN models but treated them as a black box. It also matters that the explainer sticks to the classical foundation: it first explains convolutional networks, and promises to move on to vision transformers in the next piece. For teaching, this is a logical sequence, from understandable local filters to more modern architectures.
- how convolutions pick out local features in an image
- why a network needs channels, depth, stride and pooling
- why kernel size and layer design affect the result more than raw numbers do
- how to evaluate a model not only by accuracy but also by the cost of running it
This format is especially useful now, when the industry's attention is on generative models and agents, and fundamental CV mechanics often stay off-screen. Yet these mechanics underpin many applied systems, from OCR and defect detection to medical image analysis and video analytics. If a team builds a product with visual input, understanding CNNs helps it spot limitations earlier, choose an architecture more sensibly and avoid overpaying for a model "reserve" that brings no gain in the real task.
What this means
The Yandex Praktikum piece is a reminder of a simple point: computer vision still rests not only on fashionable terms but on an understanding of basic architectures. For developers and product teams, it is a signal to look more often at model structure, data and environment constraints, rather than at a single number in a spec sheet.
- Nov 2, 2026Karpathy builds a YouTube clone with 6454 videos from Hacker News recommendations in two hours
- Nov 2, 2026Karpathy used Claude to build HackerTube from 6,454 videos recommended on Hacker News
- Nov 2, 2026The Verge reviewer builds a $50 Meta Muse Charm alternative with Claude Code
- Nov 2, 20268 Skills for video in Claude Code: from 244 pixel effects to rough-cut editing
Key Questions Answered
How CNNs see?
A convolutional network treats a picture not as a single whole object but as a grid of pixels that small filters slide across. Each filter looks for a local pattern: an edge, a corner, a repeating texture or a simple contrast. Because the same set of weights is reused across different parts of the image, the network learns to find familiar features regardless of where they sit in the frame. This is what makes CNNs practical for vision tasks: they extract structure rather than simply memorizing the whole picture. The features are then assembled into a hierarchy. Lower layers
Why few parameters can be enough?
One of the article's central points is that a bigger model does not automatically become a better one. Parameter count shows the size of a network, but says almost nothing about how well the architecture was chosen, how carefully the data was prepared, or whether the model suits a specific task. For classifying defects on a production line, for medical images or for cameras in a mobile device, the winner is not the heaviest network but the one that delivers the required accuracy at a reasonable cost in memory, speed and robustness. "Many parameters" does not always mean "th
Who this explainer is for?
In format, this is neither a scientific publication nor an ad for a course, but a practical introduction to the mechanics of computer vision. The author explicitly addresses two audiences: those just entering CV, and those who have already used off-the-shelf CNN models but treated them as a black box. It also matters that the explainer sticks to the classical foundation: it first explains convolutional networks, and promises to move on to vision transformers in the next piece. For teaching, this is a logical sequence, from understandable local filters to more modern archite
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.