AWS explains how to scale AI agent memory with namespace patterns in AgentCore Memory
AWS has released a detailed guide to organizing AI agent memory in AgentCore Memory, the Bedrock component that stores long-term context in scalable systems. It describes five namespace patterns, from user-scoped to multi-tenant hierarchies, and three data retrieval strategies. The service also integrates natively with AWS IAM, so teams can control agents' access to memory with the same policies they use for the rest of their infrastructure.
AI-processed from AWS Machine Learning Blog; edited by Hamidun News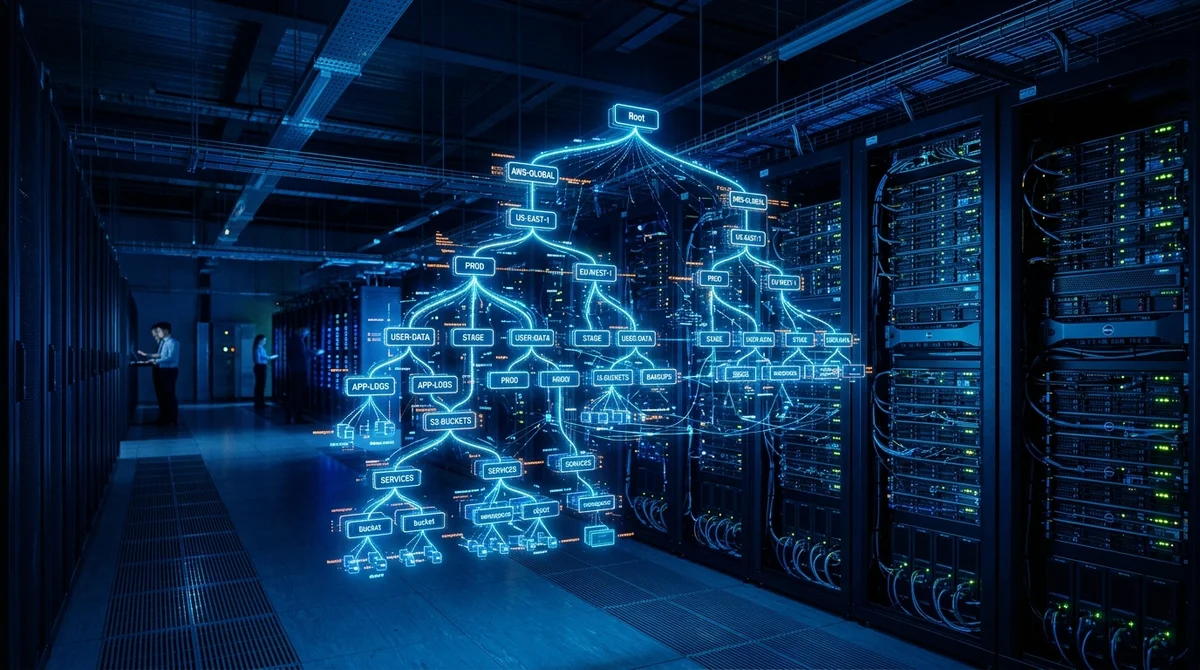
AWS has published a guide to organizing AI agent memory in AgentCore Memory, a service on the Bedrock platform for storing and structuring long-term context in scalable agent systems.
What is AgentCore Memory
AgentCore Memory is one of the components of AWS Bedrock AgentCore, which appeared in 2025 in response to growing demands for production-grade agent systems. The service addresses a specific problem: in multi-agent architectures, you cannot simply keep context in variables or a session. Data must be available across requests, agents and users at the same time.
The key abstraction is the namespace, which defines who owns a given piece of memory and who can read it. Without a clear namespace structure, agents start mixing the context of different users or lose access to the data they need.
Namespace hierarchy patterns
The right namespace structure determines the speed and accuracy of memory retrieval. AWS describes five basic patterns:
- User-scoped: a separate namespace for each user. Full isolation, with no overlap between accounts.
- Session-scoped: memory lives only within a single session. Suited to short-term tasks that do not require long-term storage.
- Project-scoped: several agents share common memory within one project or workflow.
- Tenant-scoped: for SaaS products, strict isolation between customers at the infrastructure level.
- Hierarchical mix: multi-level combinations, for example `tenant/user/project`, for complex multi-tenant systems.
For most production systems, AWS recommends a hierarchical approach with two to three levels: it offers flexibility without excessive query complexity.
Data retrieval patterns
Choosing a retrieval strategy matters as much as the storage structure. Vector semantic search is not the only option. AgentCore Memory supports several modes: direct lookup by key (fast when the namespace structure is planned in advance), semantic search (for fuzzy queries such as "what did the user say about their preferences"), and a hybrid mode, where filtering by namespace first narrows the search space and semantic search then runs within it.
The hybrid approach is especially valuable with large volumes of memory: pre-filtering reduces latency and improves the accuracy of results.
Access control through IAM
Native integration with AWS IAM is one of the main arguments for AgentCore Memory over custom solutions. Access to a namespace is managed with the same policies and roles as the rest of the AWS infrastructure, without a separate authorization system for agent memory. In practice, this makes it possible to build a clear access model:
- An agent reads only its own user's namespace and cannot see other users' data
- An orchestrator agent gets read-write access to all namespaces in a project
- A CI/CD service account deletes temporary namespaces without access to user data
- CloudTrail audit logs automatically record every agent access to memory
This model matters especially in regulated industries such as banking, healthcare and law, where data isolation between clients is a legal requirement, not a recommendation.
What this means
AWS is steadily closing infrastructure gaps in production-grade agent systems. The namespace patterns and IAM integration in AgentCore Memory tackle one of the most painful problems of multi-agent architectures: who can read what from shared memory, and when. Teams get ready-made patterns instead of custom solutions, and enterprise customers get security compliance out of the box.
- Nov 2, 2026The Verge reviewer builds a $50 Meta Muse Charm alternative with Claude Code
- Oct 31, 2026Worldwide Express hands disputed invoices to AI agents and cuts unresolved disputes by 75%
- Oct 30, 2026AWS gives coding agents a live site preview straight from an isolated session
- Oct 30, 2026Agent traffic on Zocdoc is up 30x since July, and ChatGPT faces two health lawsuits
Key Questions Answered
What is AgentCore Memory?
AgentCore Memory is one of the components of AWS Bedrock AgentCore, which appeared in 2025 in response to growing demands for production-grade agent systems. The service addresses a specific problem: in multi-agent architectures, you cannot simply keep context in variables or a session. Data must be available across requests, agents and users at the same time. The key abstraction is the namespace, which defines who owns a given piece of memory and who can read it. Without a clear namespace structure, agents start mixing the context of different users or lose access to the d
What are the key details on Namespace hierarchy patterns?
The right namespace structure determines the speed and accuracy of memory retrieval. AWS describes five basic patterns: User-scoped: a separate namespace for each user. Full isolation, with no overlap between accounts. Session-scoped: memory lives only within a single session. Suited to short-term tasks that do not require long-term storage. Project-scoped: several agents share common memory within one project or workflow. Tenant-scoped: for SaaS products, strict isolation between customers at the infrastructure level. Hierarchical mix: multi-level combinations, for example
What are the key details on Data retrieval patterns?
Choosing a retrieval strategy matters as much as the storage structure. Vector semantic search is not the only option. AgentCore Memory supports several modes: direct lookup by key (fast when the namespace structure is planned in advance), semantic search (for fuzzy queries such as "what did the user say about their preferences"), and a hybrid mode, where filtering by namespace first narrows the search space and semantic search then runs within it. The hybrid approach is especially valuable with large volumes of memory: pre-filtering reduces latency and improves the accurac
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.