AWS explains how to speed up Llama 3.2 Vision fine-tuning on data stored in S3
AWS did not unveil a new model. It showed a working way to fine-tune multimodal LLMs faster on data stored in S3. In the example, the team links SageMaker Unified Studio, Catalog and S3, then uses that setup to fine-tune Llama 3.2 11B Vision Instruct for visual question answering. For companies, the signal matters: unstructured archives can be plugged into an ML pipeline without extra manual assembly.
AI-processed from AWS Machine Learning Blog; edited by Hamidun News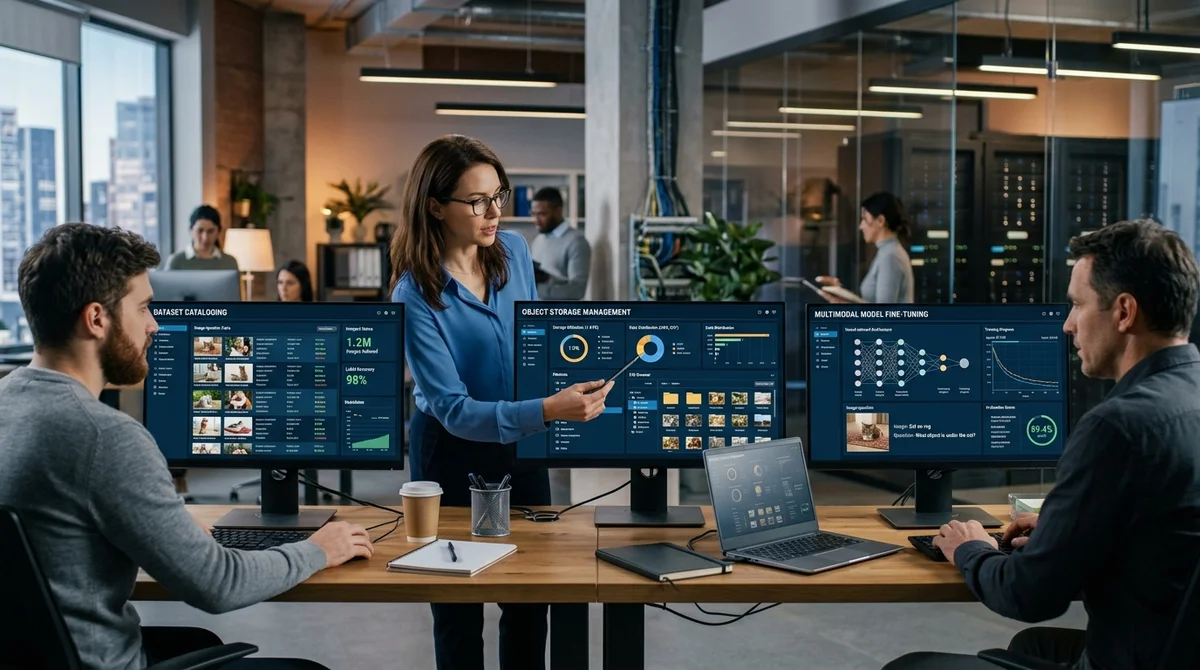
AWS has shown a practical scenario for working with unstructured data in the SageMaker ecosystem. The company described how to connect Amazon S3 to SageMaker Catalog and Unified Studio, then use that setup to fine-tune the Llama 3.2 11B Vision Instruct model for visual question answering tasks.
How the setup works
The case rests on an integration AWS announced last year: Amazon SageMaker Unified Studio can work with ordinary S3 buckets, not only with datasets prepared separately inside the ML environment. For teams this is an important shift, because most useful material sits in object storage: images, PDFs, scans, presentations, internal documents, exports and other unstructured files.
Previously, an extra manual layer often appeared between storage and model training: transfer, duplication, labeling and separate cataloging. Now AWS shows a more direct scheme. S3 serves as the base storage, SageMaker Catalog helps describe and organize the data, and Unified Studio becomes a shared workspace for analysts and ML engineers. In this approach, data does not just "sit in a bucket" but becomes an accessible, governed asset inside the pipeline. That reduces friction between teams and lets them move faster from raw files to a model experiment, without building separate infrastructure around each project.
What the example shows
For the demonstration, AWS took Llama 3.2 11B Vision Instruct and the task of visual question answering, or VQA. In this scenario the model must look at an image and answer questions about its content. Such tasks appear in document processing, e-commerce, support, inspections and internal knowledge bases, where it matters not just to store an image but to extract an answer from it in clear text form. For this kind of fine-tuning it is especially critical that visual data and accompanying annotations are gathered in one clear environment.
The practical value of the post is that AWS emphasizes not model benchmarks but the speed of assembling a working process. For many companies the bottleneck is not choosing the LLM itself but the path from "we have an archive of files" to "we have launched fine-tuning for a specific business task." Integrating S3 with Catalog and Unified Studio shortens exactly this path. Instead of scattered manual steps, the team gets a more connected process that is easier to repeat, document and scale to other datasets.
- Existing S3 buckets can be used without a separate migration to new storage
- The team gets a single space for working with data, analytics and ML experiments
- Unstructured files are easier to turn into reusable datasets
- Multimodal models can be adapted to applied scenarios such as VQA
- The volume of manual operations between data storage and the start of fine-tuning drops
AWS does not promise, however, that fine-tuning is now a "one-click" task. Result quality still depends on labeling, data cleanliness, how the question is framed and how well the base set of examples is chosen. But the infrastructure part gets simpler: object storage stops being a passive archive and becomes a working source for ML and analytics. For companies with large volumes of images and documents, this can noticeably shorten the time to a first useful prototype.
What this means
AWS is pushing the market from abstract talk about model capabilities toward the practical assembly of a data-to-model pipeline. The takeaway for business is simple: advantage increasingly comes not only from choosing a strong LLM but from how fast a team can connect its unstructured data, describe it and turn it into a managed loop for repeatable fine-tuning. The fewer manual seams between storage, catalog and training, the faster applied models appear for specific processes.
- Nov 2, 2026Meta's Muse assistant keeps dossiers on loved ones and gets root on Ubuntu by default
- Nov 2, 2026The Verge reviewer builds a $50 Meta Muse Charm alternative with Claude Code
- Nov 1, 2026MoneyGate safety layer blocked all 42 fraudulent requests to local AI models
- Oct 31, 2026Open-source LLM gateway KTMS 1.0 plugs your own GPUs into the cloud and survives outages
Key Questions Answered
How the setup works?
The case rests on an integration AWS announced last year: Amazon SageMaker Unified Studio can work with ordinary S3 buckets, not only with datasets prepared separately inside the ML environment. For teams this is an important shift, because most useful material sits in object storage: images, PDFs, scans, presentations, internal documents, exports and other unstructured files. Previously, an extra manual layer often appeared between storage and model training: transfer, duplication, labeling and separate cataloging. Now AWS shows a more direct scheme. S3 serves as the base
What the example shows?
For the demonstration, AWS took Llama 3.2 11B Vision Instruct and the task of visual question answering, or VQA. In this scenario the model must look at an image and answer questions about its content. Such tasks appear in document processing, e-commerce, support, inspections and internal knowledge bases, where it matters not just to store an image but to extract an answer from it in clear text form. For this kind of fine-tuning it is especially critical that visual data and accompanying annotations are gathered in one clear environment. The practical value of the post is t
What this means?
AWS is pushing the market from abstract talk about model capabilities toward the practical assembly of a data-to-model pipeline. The takeaway for business is simple: advantage increasingly comes not only from choosing a strong LLM but from how fast a team can connect its unstructured data, describe it and turn it into a managed loop for repeatable fine-tuning. The fewer manual seams between storage, catalog and training, the faster applied models appear for specific processes.
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.