LLM aggregators: how to choose working free models and not misreport the result
Choosing a free model from a list sounds simple. In practice, half the models are unstable, some disappear from the listing, and quality varies. The answer is not an endless catalog but a smart backend with cleanup, health checks, fallback across brands, and an honest actual_model in the response.
AI-processed from Habr AI; edited by Hamidun News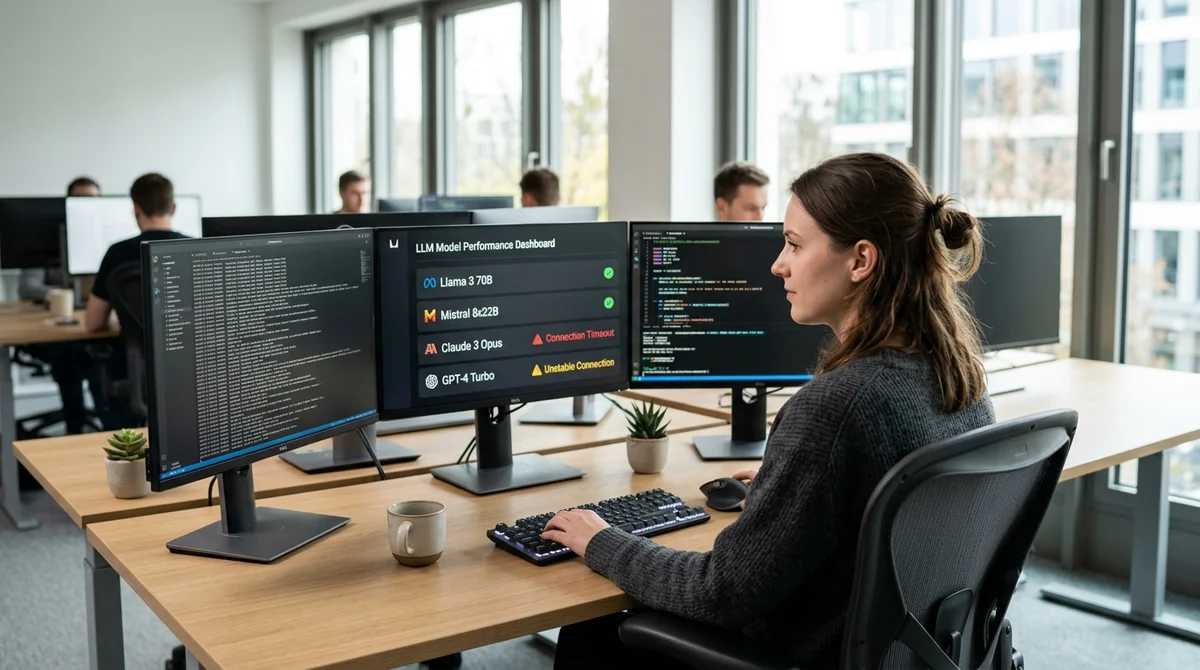
If a project requires choosing an LLM, most often you take the most obvious path: a long list of models, pick one, send a request. It works over short distances. Over long distances, it starts to break.
Where the Simple Approach Breaks
Problems don't appear in the interface, but in provider behavior and the models themselves:
- Unstable free models — listed as free, but respond unreliably, disappear during provider downtime
- Models disappear — available yesterday, today the provider removed it or closed it to new users
- Quality degradation — formally alive, but only suitable for demo or simple tasks
- Frontend-backend mismatch — the interface list is a day or two outdated, while the backend knows a different reality
- Errors and redirects — you requested one model, got an error, or the response came from a completely different model
The main problem: the interface doesn't know which model actually responded. The user selected Claude 3.5, but the response came from Gemini — and they won't find out. This creates confusion: if the response quality doesn't match the selected model, the user loses trust.
A Rigid Engineering Loop Instead of a Catalog
The solution is built not through an endless list, but through backend control:
Step 1: list cleanup. The backend receives a raw list of models from the provider, filters it — keeps only suitable free options, removes unstable ones, eliminates duplicates. You can add health checks — periodically ping each model and see if it's alive.
Step 2: one model per brand. Even if OpenAI has 5 free models in the list, the frontend gets one, the most stable. This simplifies choice for the user and reduces the chance of hitting a bad model.
Step 3: fallback between brands. During an actual request — if the first model returned an error, automatically try the second, then the third. The user won't know about the failure, for them it's just a bit slower.
Step 4: honesty in the response. Return not just the generated text, but also `actual_model` — which model actually generated this. Now the interface can honestly tell the user: "The response is from GPT 4o mini, because the primary one was in downtime."
"The problem is not how to nicely show a list of models.
The problem is how to build a system that chooses live free models and doesn't lie about the result" — that's the essence of the task.
This turns an unstable catalog into a predictable loop. The provider removed a model — the backend will notice it on the next check and update the list on the frontend. The model went down — fallback kicks in, the user gets a response from another provider.
What This Means
Choosing an LLM stops being a UI task and becomes an engineering task — with data cleanup, health checks, fallback logic, and honest tracking. For the product, it means reliability and fewer support questions. For the user — the choice works, responses arrive, the interface doesn't lie.
- Oct 28, 2026Wired Tested 6 AI Agents in a Day: Dots Leads, Gemini Spark Fails at Lunch
- Oct 28, 2026Anthropic Turns Claude Code Into a Platform: Claude Mods Flip the Agent Harness
- Oct 28, 2026Liquid AI releases LFM2.5-24B-A2B: an agent model with 2B active parameters
- Oct 28, 2026OpenAI Releases Decisions API: Agent Decisions Up to 10x Faster
Key Questions Answered
Where the Simple Approach Breaks?
Problems don't appear in the interface, but in provider behavior and the models themselves: Unstable free models — listed as free, but respond unreliably, disappear during provider downtime Models disappear — available yesterday, today the provider removed it or closed it to new users Quality degradation — formally alive, but only suitable for demo or simple tasks Frontend-backend mismatch — the interface list is a day or two outdated, while the backend knows a different reality Errors and redirects — you requested one model, got an error, or the response came from a comple
What are the key details on A Rigid Engineering Loop Instead of a Catalog?
The solution is built not through an endless list, but through backend control: Step 1: list cleanup. The backend receives a raw list of models from the provider, filters it — keeps only suitable free options, removes unstable ones, eliminates duplicates. You can add health checks — periodically ping each model and see if it's alive. Step 2: one model per brand. Even if OpenAI has 5 free models in the list, the frontend gets one, the most stable. This simplifies choice for the user and reduces the chance of hitting a bad model. Step 3: fallback between brands. During an act
What This Means?
Choosing an LLM stops being a UI task and becomes an engineering task — with data cleanup, health checks, fallback logic, and honest tracking. For the product, it means reliability and fewer support questions. For the user — the choice works, responses arrive, the interface doesn't lie.
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.