From TF-IDF to Word2vec: Beeline Cloud released a collection on embeddings
Beeline Cloud released a collection of free guides on embeddings. The materials cover TF-IDF, Word2vec, cosine similarity for semantic search, and vectorization algorithms with clear diagrams. Suitable for developers and ML specialists.
AI-processed from Habr AI; edited by Hamidun News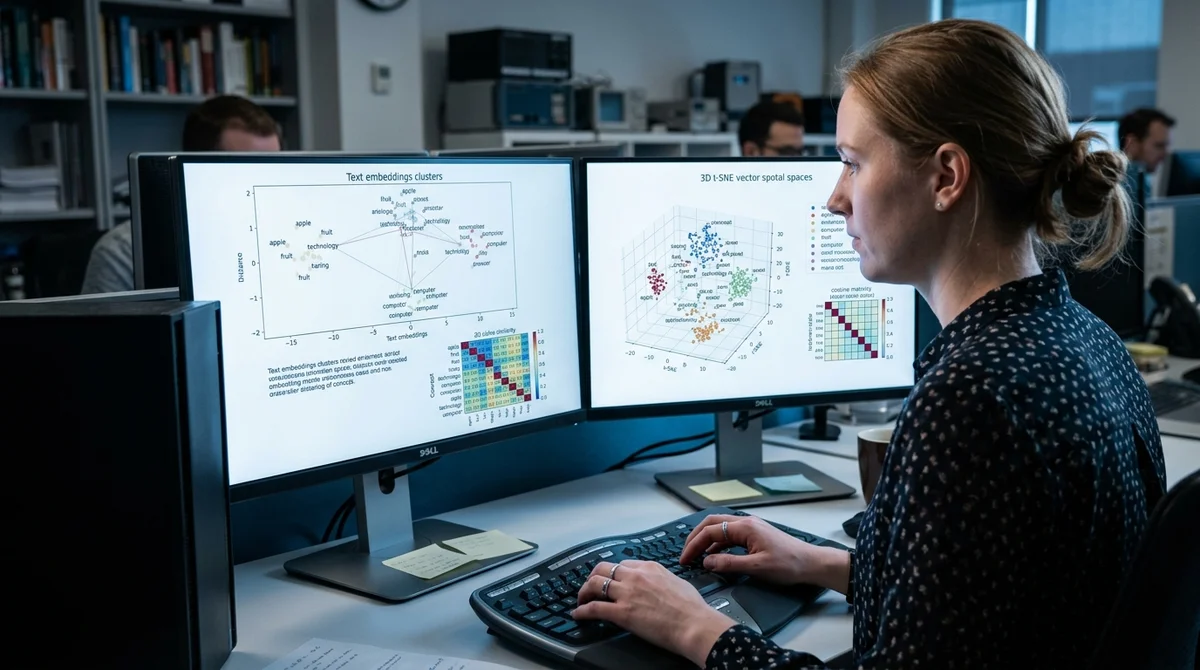
Beeline Cloud has published a free collection of guides on embeddings and vector representations. The materials will help developers and machine learning specialists understand the technology behind modern search, recommendations, and language models.
What's included in the collection
The guides cover the full spectrum of techniques — from classical approaches of the 2010s to practices used in LLMs and RAG systems.
- TF-IDF — weighting the importance of words in text, the foundation for searching relevant documents
- Word2vec — transforming words into dense vectors of dimension 100-300 that reflect semantic relationships
- Cosine similarity — computing proximity between vectors, a basic tool for semantic search
- Vectorization algorithms — techniques for transforming text and structured data into numerical representations
- Visual diagrams — visual schemes that explain each method without complex mathematics
The collection is titled "Embeddings Explained with Dog Examples," which references a popular explanatory style: complex concepts are broken down into intuitive, accessible examples.
Where embeddings work in real systems
Embeddings are a critical component of the modern ML stack. They are used in recommendation systems (Netflix, Spotify), search (Google, Yandex), text classification (spam filters), autocomplete, and generative models (ChatGPT works with embeddings at the token level). Cloud services like Beeline Cloud, AWS, and Google Cloud actively offer ready-made APIs for working with vector databases (Pinecone, Weaviate, Milvus), which means: the technology has moved from the laboratory into production.
Target audience
The collection is useful for developers who want to understand how semantic search works internally, start working with vector databases, integrate RAG (Retrieval-Augmented Generation) into their applications, or prepare for interviews at ML companies.
What this means
Embeddings are becoming a tool not only for ML specialists but also for regular developers. When cloud providers invest resources in educational materials, it's a signal: the technology has matured for widespread adoption. Companies that now train their teams to work with vector search will gain a competitive advantage.
- Oct 28, 2026Keystone removes the model name from code: open-source LLM gateway adds 0.64 ms
- Oct 28, 2026Wired Tested 6 AI Agents in a Day: Dots Leads, Gemini Spark Fails at Lunch
- Oct 28, 2026Anthropic Turns Claude Code Into a Platform: Claude Mods Flip the Agent Harness
- Oct 28, 2026Liquid AI releases LFM2.5-24B-A2B: an agent model with 2B active parameters
Key Questions Answered
What's included in the collection?
The guides cover the full spectrum of techniques — from classical approaches of the 2010s to practices used in LLMs and RAG systems. TF-IDF — weighting the importance of words in text, the foundation for searching relevant documents Word2vec — transforming words into dense vectors of dimension 100-300 that reflect semantic relationships Cosine similarity — computing proximity between vectors, a basic tool for semantic search Vectorization algorithms — techniques for transforming text and structured data into numerical representations Visual diagrams — visual schemes that ex
Where embeddings work in real systems?
Embeddings are a critical component of the modern ML stack. They are used in recommendation systems (Netflix, Spotify), search (Google, Yandex), text classification (spam filters), autocomplete, and generative models (ChatGPT works with embeddings at the token level). Cloud services like Beeline Cloud, AWS, and Google Cloud actively offer ready-made APIs for working with vector databases (Pinecone, Weaviate, Milvus), which means: the technology has moved from the laboratory into production.
What are the key details on Target audience?
The collection is useful for developers who want to understand how semantic search works internally, start working with vector databases, integrate RAG (Retrieval-Augmented Generation) into their applications, or prepare for interviews at ML companies.
Build & Ship Production AI Agents Without Boilerplate Code
Start your free 72-hour trial at Hamidun Academy (academy.hamidun.com) — interactive lessons on Claude Code & Cursor, live Tech Radar, and production agent templates.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.