Anthropic builds a tool that translates Claude's internal 'thoughts' into plain language
Anthropic has introduced Natural Language Autoencoders, a method that converts Claude's internal activations into text explanations. The technique lets researchers see in real time how the model processes information and makes decisions, turning the neural network's black box into a more transparent mechanism. Instead of guessing from the final answer, researchers can now look at what the model is "thinking" internally.
AI-processed from MarkTechPost; edited by Hamidun News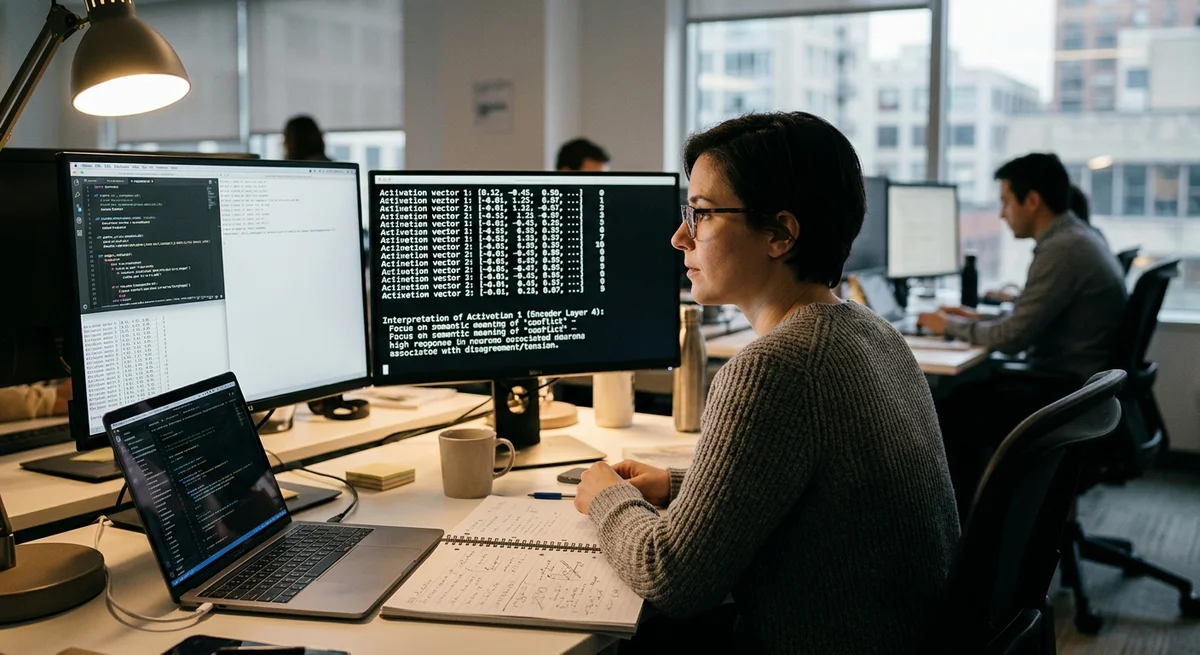
Anthropic has developed Natural Language Autoencoders, a new technique that translates the internal activations of the Claude neural network into text explanations. This means it is now possible to see what the model "thinks" internally, instead of guessing from its final answer.
What are Natural Language Autoencoders?
When you send Claude a message, it passes through a chain of hidden transformations. The text is encoded into long vectors of numbers called activations. This is the level at which the model analyzes meaning, connects information and makes decisions.
The problem is that, to a human, these vectors are just numbers. Anthropic has built a tool that takes these numerical representations and converts them back into natural language: explanations a person can understand of what happened at each stage of processing.
How does it work?
Natural Language Autoencoders work in two stages. First, an encoder compresses the model's activations into a compact representation. Then a decoder unfolds that representation into text.
The core idea is that text explanations are far more informative for analysis than trying to interpret the raw vectors. Instead of piles of numbers, you get sentences like "the model noticed this is a math question" or "here it needs to check the context from the previous message".
Why does it matter?
Model interpretability is one of the main problems in AI. Until now, neural networks have mostly remained black boxes. With this tool, Anthropic moves toward transparency:
- Debugging: you can see at which stage the model started to make mistakes
- Safety: it is easier to spot undesirable behavior at the activation level
- Training: researchers get a better grasp of the model's internal logic
- Trust: transparency strengthens users' confidence in AI
What does it mean?
Natural Language Autoencoders are not just a research project. They are a first practical step toward making large language models stop being black boxes. The better we understand how neural networks think, the better we can control and improve them. For developers, this opens up new possibilities for diagnostics and optimization.
- Nov 2, 2026mcp-linter finds 18 undescribed parameters in Anthropic's filesystem server
- Nov 2, 2026The Verge reviewer builds a $50 Meta Muse Charm alternative with Claude Code
- Nov 2, 20268 Skills for video in Claude Code: from 244 pixel effects to rough-cut editing
- Nov 1, 2026Local models lose to Opus and Codex: 0.21 on a MacBook versus 1.00 for Codex
Key Questions Answered
What are Natural Language Autoencoders?
When you send Claude a message, it passes through a chain of hidden transformations. The text is encoded into long vectors of numbers called activations. This is the level at which the model analyzes meaning, connects information and makes decisions. The problem is that, to a human, these vectors are just numbers. Anthropic has built a tool that takes these numerical representations and converts them back into natural language: explanations a person can understand of what happened at each stage of processing.
How does it work?
Natural Language Autoencoders work in two stages. First, an encoder compresses the model's activations into a compact representation. Then a decoder unfolds that representation into text. The core idea is that text explanations are far more informative for analysis than trying to interpret the raw vectors. Instead of piles of numbers, you get sentences like "the model noticed this is a math question" or "here it needs to check the context from the previous message".
Why does it matter?
Model interpretability is one of the main problems in AI. Until now, neural networks have mostly remained black boxes. With this tool, Anthropic moves toward transparency: Debugging: you can see at which stage the model started to make mistakes Safety: it is easier to spot undesirable behavior at the activation level Training: researchers get a better grasp of the model's internal logic Trust: transparency strengthens users' confidence in AI
What does it mean?
Natural Language Autoencoders are not just a research project. They are a first practical step toward making large language models stop being black boxes. The better we understand how neural networks think, the better we can control and improve them. For developers, this opens up new possibilities for diagnostics and optimization.
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.