Anthropic created a tool to translate Claude's thoughts into human language
Anthropic introduced Natural Language Autoencoders, a method for converting Claude's internal activations into textual explanations. This development makes it possible to see in real time how the model processes information and makes decisions, turning the neural network's black box into a transparent mechanism.
AI-processed from MarkTechPost; edited by Hamidun News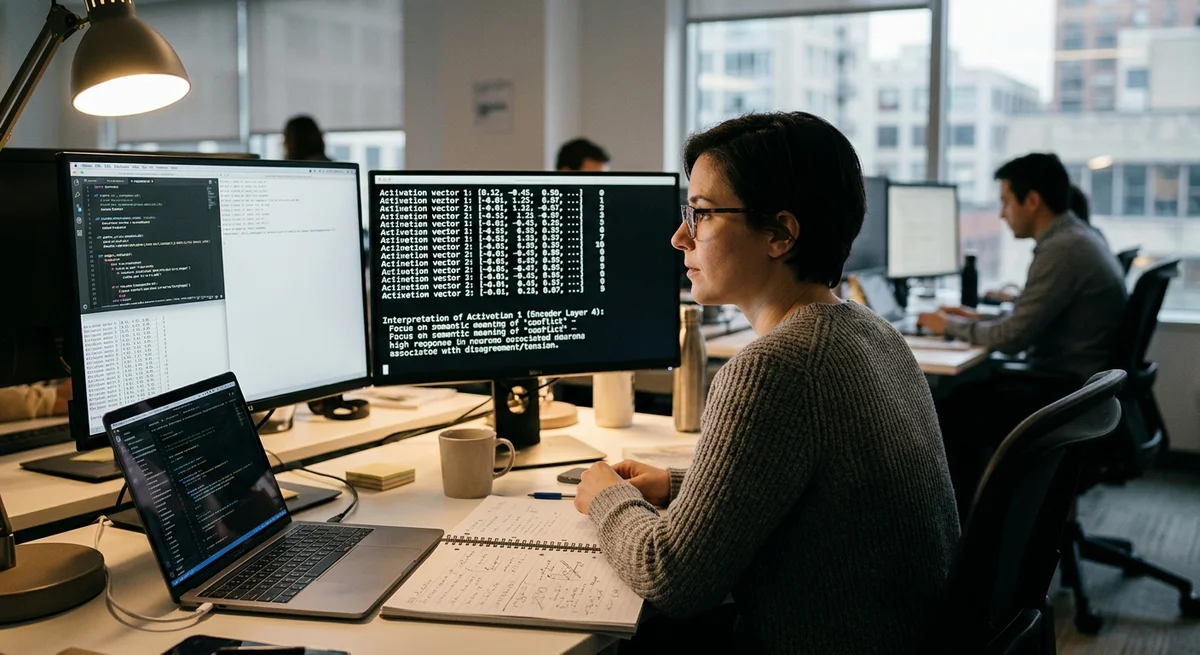
Anthropic has developed Natural Language Autoencoders — a new technique that translates the internal activations of the Claude neural network into textual explanations. This means you can now see what the model is "thinking" internally, instead of guessing based on the final response.
What are Natural Language Autoencoders?
When you write a message to Claude, it goes through a series of hidden transformations. The text is encoded into long vectors of numbers, called activations. It's at this level that the model analyzes meaning, connects information, and makes decisions. The problem is that these vectors are just numbers for humans. Anthropic created a tool that takes these numerical representations and transforms them back into natural language — into understandable explanations of what was happening at each stage of processing.
How does it work?
Natural Language Autoencoders work in two stages. First, the encoder compresses the model's activations into a compact representation. Then, the decoder unfolds this representation into text. The essence of the idea is that textual explanations are much more informative for analysis than trying to interpret the vectors themselves. Instead of pools of numbers, you get sentences like: "the model noticed this is a question about mathematics" or "here we need to check the context from the previous message".
Why is this important?
Model interpretability is one of the main challenges in AI. So far, neural networks have remained largely black boxes. Anthropic is taking a step toward transparency with this tool:
- Debugging — you can see at which stage the model started to make errors
- Security — it's easier to identify unwanted behavior at the activation level
- Research — researchers better understand the internal logic of the model
- Trust — transparency strengthens user confidence in AI
What does this mean?
Natural Language Autoencoders are not just a research project. This is the first practical step toward making large language models stop being black boxes. The better we understand how neural networks think, the better we can control and improve them. For developers, this opens up new possibilities for diagnostics and optimization.
- Oct 28, 2026A 2015 CNN Beat GPT-6 Astra and Claude Fable 5.1 at Skin Cancer Diagnosis
- Oct 28, 2026Keystone removes the model name from code: open-source LLM gateway adds 0.64 ms
- Oct 28, 2026Wired Tested 6 AI Agents in a Day: Dots Leads, Gemini Spark Fails at Lunch
- Oct 28, 2026Anthropic files for IPO: $16.3 billion in revenue in six months, ticker ANT
Key Questions Answered
What are Natural Language Autoencoders?
When you write a message to Claude, it goes through a series of hidden transformations. The text is encoded into long vectors of numbers, called activations. It's at this level that the model analyzes meaning, connects information, and makes decisions. The problem is that these vectors are just numbers for humans. Anthropic created a tool that takes these numerical representations and transforms them back into natural language — into understandable explanations of what was happening at each stage of processing.
How does it work?
Natural Language Autoencoders work in two stages. First, the encoder compresses the model's activations into a compact representation. Then, the decoder unfolds this representation into text. The essence of the idea is that textual explanations are much more informative for analysis than trying to interpret the vectors themselves. Instead of pools of numbers, you get sentences like: "the model noticed this is a question about mathematics" or "here we need to check the context from the previous message".
Why is this important?
Model interpretability is one of the main challenges in AI. So far, neural networks have remained largely black boxes. Anthropic is taking a step toward transparency with this tool: Debugging — you can see at which stage the model started to make errors Security — it's easier to identify unwanted behavior at the activation level Research — researchers better understand the internal logic of the model Trust — transparency strengthens user confidence in AI
What does this mean?
Natural Language Autoencoders are not just a research project. This is the first practical step toward making large language models stop being black boxes. The better we understand how neural networks think, the better we can control and improve them. For developers, this opens up new possibilities for diagnostics and optimization.
Build & Ship Production AI Agents Without Boilerplate Code
Start your free 72-hour trial at Hamidun Academy (academy.hamidun.com) — interactive lessons on Claude Code & Cursor, live Tech Radar, and production agent templates.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.