MELT-1: how Metabolic AI tests agents for survival
Habr published an article about MELT-1, a benchmark that measures not MMLU but how long an AI agent survives under distribution drift. Metabolic AI posted a 1600× better result than Llama-7B INT8 on the manipulation task. The benchmark is open: scenarios, oracle, code.
AI-processed from Habr AI; edited by Hamidun News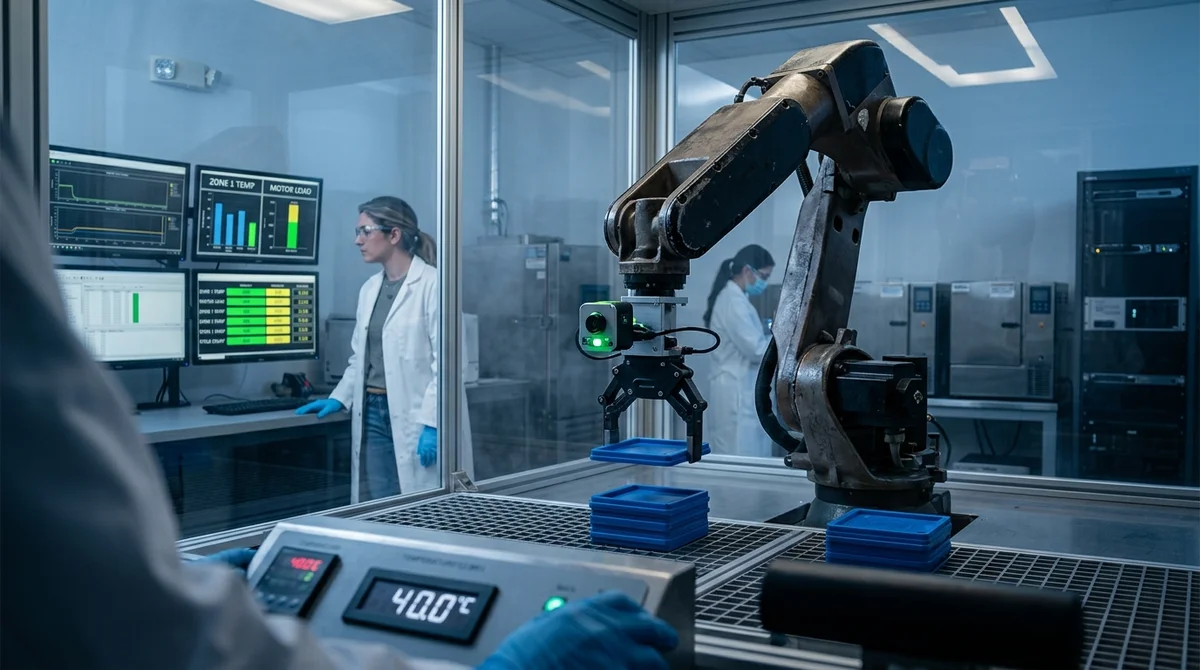
MELT-1 — this is not MMLU and not MMLU Pro. This is a new open benchmark for testing AI agents under real conditions: not "what does the model know," but "how many hours will it survive when everything changes around it."
Three axes instead of one number
Conventional benchmarks (MMLU, ARC, GPQA) assume ideal conditions: static questions, stable data distribution. MELT-1 measures three things at once:
- Computation economy: how much it costs to maintain an agent in combat conditions ($/1M successful solutions)
- Survival under drift: how many hours the agent works without retraining before it starts making errors
- Latency under stress: p99 time from sensor to actuator at 40°C over 30 consecutive days of inference, 5 seeds, two temperature profiles.
This is not a lab test — this is a scenario in which a real robot must work day and night, summer and winter.
Results: 1600× difference
On closed-loop manipulation (robot grasps and stacks objects), Metabolic AI — an architecture without a transformer — outperformed Llama-class 7B INT8 by 9.4× on cost and by 8.5× on survival under drift. Compositely: 1600×.
This is not because Llama is bad. This is because 7B transformers are designed for static knowledge retrieval, not for an embodied agent that needs to stay hot 24/7.
"Transformers die after 11 hours under drift," the authors write.
Openness as a standard
The Metabolic AI architecture is closed (patent under examination), but the benchmark is fully open: harness, test scenes, oracle, sensitivity scripts, VAE encoder of drift for reproduction. Methodology in PDF with a section on threats to validity. Researchers invite others to run their agents and place the results alongside.
This is how science in deep learning should be done: closed IP, open benchmarks, reproducibility through code.
What this means
MELT-1 may become a new standard for robotics and embodied AI. MMLU shows whether a model is "smart." MELT-1 shows whether it is "viable."
- Oct 29, 2026Liquid AI releases LFM3: six multimodal 2B models with a 256K context window
- Oct 28, 2026Wired Tested 6 AI Agents in a Day: Dots Leads, Gemini Spark Fails at Lunch
- Oct 28, 2026Liquid AI releases LFM2.5-24B-A2B: an agent model with 2B active parameters
- Oct 28, 2026Meta releases Muse Spark Open: 816B parameters and the lead among US open-weight models
Key Questions Answered
What are the key details on Three axes instead of one number?
Conventional benchmarks (MMLU, ARC, GPQA) assume ideal conditions: static questions, stable data distribution. MELT-1 measures three things at once: Computation economy: how much it costs to maintain an agent in combat conditions ($/1M successful solutions) Survival under drift: how many hours the agent works without retraining before it starts making errors Latency under stress: p99 time from sensor to actuator at 40°C over 30 consecutive days of inference, 5 seeds, two temperature profiles. This is not a lab test — this is a scenario in which a real robot must work day an
What are the key details on Results: 1600× difference?
On closed-loop manipulation (robot grasps and stacks objects), Metabolic AI — an architecture without a transformer — outperformed Llama-class 7B INT8 by 9.4× on cost and by 8.5× on survival under drift. Compositely: 1600×. This is not because Llama is bad. This is because 7B transformers are designed for static knowledge retrieval, not for an embodied agent that needs to stay hot 24/7. "Transformers die after 11 hours under drift," the authors write.
What are the key details on Openness as a standard?
The Metabolic AI architecture is closed (patent under examination), but the benchmark is fully open: harness, test scenes, oracle, sensitivity scripts, VAE encoder of drift for reproduction. Methodology in PDF with a section on threats to validity. Researchers invite others to run their agents and place the results alongside. This is how science in deep learning should be done: closed IP, open benchmarks, reproducibility through code.
Build & Ship Production AI Agents Without Boilerplate Code
Start your free 72-hour trial at Hamidun Academy (academy.hamidun.com) — interactive lessons on Claude Code & Cursor, live Tech Radar, and production agent templates.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.