RAG Systems Break on Real Data: Retrieval Is to Blame, Not the Model
RAG pipelines often fail not because of the model but because of retrieval. When the system fetches the wrong document or the wrong chunk of text, even GPT-4 starts to hallucinate. A model is only as good as the context it is handed.
AI-processed from Habr AI; edited by Hamidun News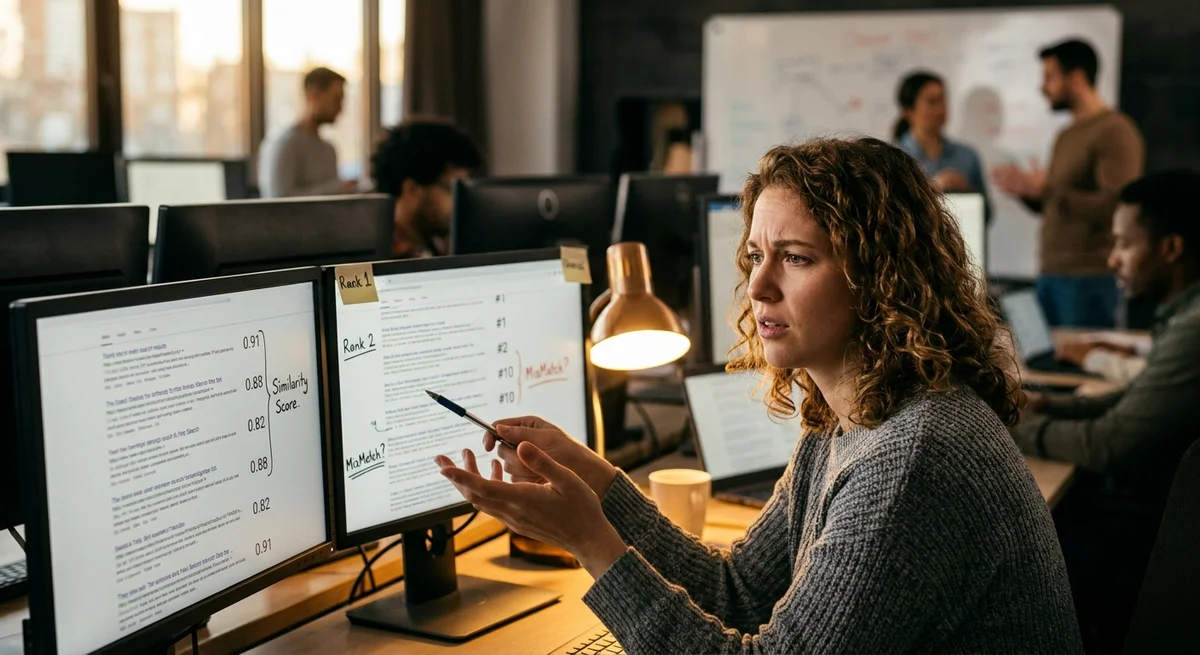
A RAG pipeline looks like magic: you upload documents, split them into chunks, generate embeddings, and plug in a vector database. You ask a question, and the model answers confidently and in detail. You show it to the client, who is delighted. But then real testing begins with actual questions, and it turns out the system misses the mark on half of them.
The RAG bottleneck
On real questions, the system often answers incorrectly. Sometimes it finds the wrong document entirely. Sometimes it finds the right document but extracts the wrong chunk of text. Sometimes it retrieves nothing relevant at all, and the model hallucinates with confidence.
It seems the problem is the model. In fact, retrieval is at fault. GPT-4 and Claude answer very well when given the right context. If the context is wrong, hallucination is guaranteed, no matter how good the model is. The model answers exactly as well as the context it is handed.
The problem isn't the models. The problem is retrieval: how we search for relevant pieces of documents in your knowledge base. This is the bottleneck through which the entire RAG pipeline passes. If retrieval gives the model the wrong context, everything else is wasted time and money.
"The model answers as well as the context it is handed."
When retrieval breaks
Retrieval can break for dozens of reasons. Here are the most common:
- Chunking is too coarse or too fine. A 512-word chunk can capture neighboring context instead of the piece you need. The question is about the returns policy, but the chunk contains a size chart description.
- Embeddings were generated for English-language data, while the question is in Russian. The semantic distance between the question vector and the document vectors is huge, so there are no matches.
- The question is reworded so that its embedding vector doesn't match the vectors in the database. You search for "return an order", but the documents say "product return", which has different semantics.
- The relevant document is found 8th out of 10, but the model was fed only the top 5 results. The needed context never makes it into the visible window.
- The index is full of duplicates and noise. Many irrelevant chunks push the correct information out of the results.
Each of these problems leads to the same outcome: the model hallucinates instead of giving the right answer.
The price of retrieval
Optimizing retrieval is not a hobby for enthusiasts. It is real, necessary work: a week or two of a developer's time spent on analysis will reveal that the system is 30-40% below expected accuracy. The cause isn't the model but the fact that retrieval searches incorrectly. On real projects this is a huge loss: time spent on RAG, money spent on infrastructure, and the system doesn't work because the document vectors don't match the question vectors.
What this means
RAG works only if retrieval works. Without that, even the best model will make mistakes. This means that before launching RAG in production, you need to invest serious time in optimizing search, testing on real data, and then iteratively improving the retrieval pipeline.
- Nov 2, 2026Karpathy builds a YouTube clone with 6454 videos from Hacker News recommendations in two hours
- Nov 2, 2026Karpathy used Claude to build HackerTube from 6,454 videos recommended on Hacker News
- Nov 2, 2026Arca gives AI agents finance tasks lasting up to 10 days, but leaves the trades to humans
- Nov 2, 2026Anthropic needs to grow revenue 32% a year to cover $850 billion in contracts
Key Questions Answered
What are the key details on The RAG bottleneck?
On real questions, the system often answers incorrectly. Sometimes it finds the wrong document entirely. Sometimes it finds the right document but extracts the wrong chunk of text. Sometimes it retrieves nothing relevant at all, and the model hallucinates with confidence. It seems the problem is the model. In fact, retrieval is at fault. GPT-4 and Claude answer very well when given the right context. If the context is wrong, hallucination is guaranteed, no matter how good the model is. The model answers exactly as well as the context it is handed. The problem isn't the mode
When retrieval breaks?
Retrieval can break for dozens of reasons. Here are the most common: Chunking is too coarse or too fine. A 512-word chunk can capture neighboring context instead of the piece you need. The question is about the returns policy, but the chunk contains a size chart description. Embeddings were generated for English-language data, while the question is in Russian. The semantic distance between the question vector and the document vectors is huge, so there are no matches. The question is reworded so that its embedding vector doesn't match the vectors in the database. You search
What are the key details on The price of retrieval?
Optimizing retrieval is not a hobby for enthusiasts. It is real, necessary work: a week or two of a developer's time spent on analysis will reveal that the system is 30-40% below expected accuracy. The cause isn't the model but the fact that retrieval searches incorrectly. On real projects this is a huge loss: time spent on RAG, money spent on infrastructure, and the system doesn't work because the document vectors don't match the question vectors.
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.