OpenAI introduces GPT-5.3-Codex-Spark based on Cerebras chips instead of Nvidia
OpenAI has taken an important step toward hardware independence by introducing GPT-5.3-Codex-Spark. For the first time in the company's history, a flagship product was trained and deployed not on Nvidia GPUs, but on Wafer Scale Engine 3 chips from startup Cerebras Systems. WSE-3 is a massive chip the size of an entire silicon wafer, with enormous computing power. This OpenAI initiative is aimed at diversifying supply chains and reducing dependence on scarce Nvidia accelerators. The shift to alternative hardware could significantly change the economics of training large language models and speed up the development of new architectures.
AI-processed from 3DNews AI; edited by Hamidun News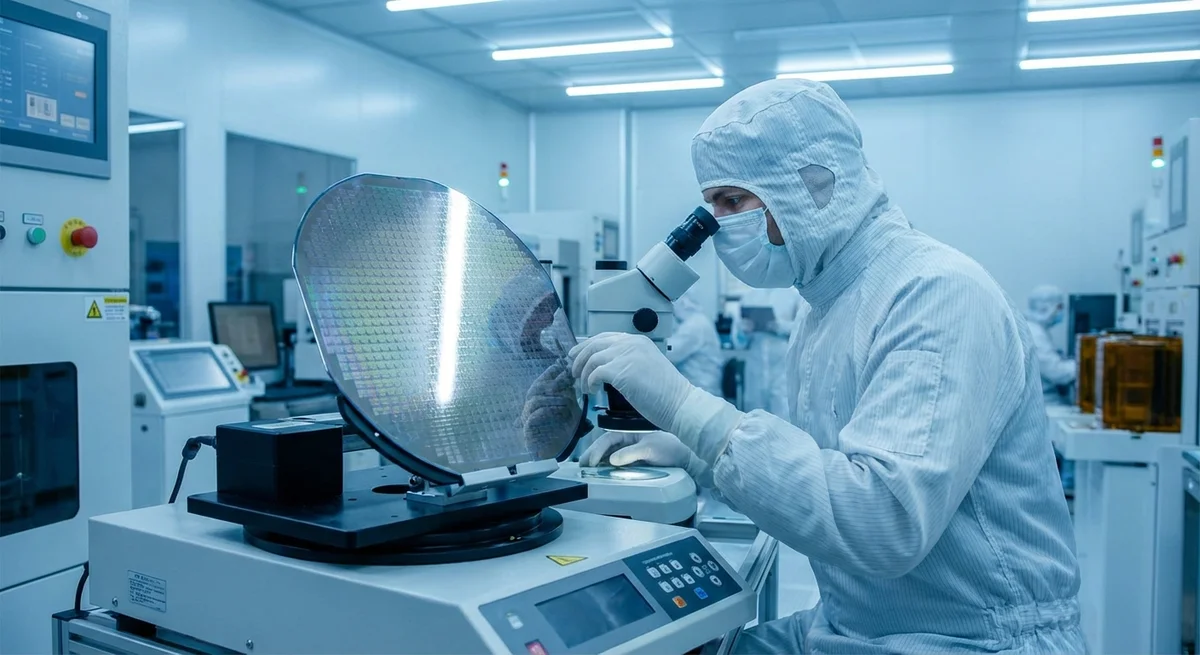
# OpenAI Abandons Nvidia. What This Means for the Future of Artificial Intelligence
In the history of large language models, a moment has arrived that many considered impossible. OpenAI unveiled GPT-5.3-Codex-Spark — the company's first flagship model that was trained and deployed not on Nvidia graphics processors, but on alternative Wafer Scale Engine 3 chips from Cerebras Systems. This step reveals not merely a technical achievement, but a turning point in the economics of artificial intelligence and the struggle for independence among the industry's most powerful companies.
Over the past five years, Nvidia has established near-monopoly control over the market for accelerators used in training neural networks. When it became clear that transformer architectures required enormous computational power, all major laboratories — from OpenAI to Meta and Google — bet on its GPUs. But dependence on a single supplier carries risk. Export restrictions to China, chip shortages, rising prices — all of this has weighed on companies trying to scale their models. OpenAI suffered silently along with everyone else, but now has decided to take action.
Cerebras Systems proposed an unusual approach. Rather than creating thousands of small processors, the company engineered the WSE-3 — a monolithic silicon crystal the size of an entire wafer, impossible to mount on a standard socket. It is not merely a chip, but an entire mini-farm on a single piece of silicon, containing over 900,000 cores. It seems this solution went against the principles of modularity, yet this is exactly what allowed Cerebras to avoid the bottlenecks of data transfer between individual processors — the primary enemy of parallel training.
When OpenAI tested training GPT-5.3-Codex-Spark on the WSE-3, the results proved unexpected. The model's convergence speed remained at the level of training on Nvidia H100, but required less synchronization and data movement between accelerators. In other words, those very hours of network idle time the company previously wasted can now be used for useful computation. This means cheaper. This means faster.
But the main point is not the technical numbers, but the strategic significance. OpenAI has demonstrated that an alternative to Nvidia exists, and that large models can be trained on chips other than theirs. This is the first serious challenge to the monopoly, and the market is already reacting. Other companies — Intel with its Gaudi, AMD with EPYC and MI300, even Google with TPU — now know there is a window of opportunity. If OpenAI can retrain a model on new hardware and achieve comparable results, so can they.
The economics of artificial intelligence will change, but not instantly. Cerebras currently cannot produce WSE-3 in the volumes that Nvidia outputs H100. Rebuilding infrastructure, rewriting code for optimization to the new architecture — all of this will take time. However, a beginning has been made. In the next two to three years, we will likely see more extravagant accelerator designs, more active experimentation with neuromorphic chips and quantum computers. Nvidia will remain a powerful player, but no longer the only one.
For ordinary ChatGPT users, this will practically change nothing — the model remains the same, its capabilities unchanged. But for the industry, the difference is enormous. OpenAI has proven that great intelligence can be built differently, and that in the race for hardware, success belongs not to those who arrived first, but to those who think faster.
- Oct 28, 2026Keystone removes the model name from code: open-source LLM gateway adds 0.64 ms
- Oct 28, 2026Wired Tested 6 AI Agents in a Day: Dots Leads, Gemini Spark Fails at Lunch
- Oct 28, 2026Anthropic Turns Claude Code Into a Platform: Claude Mods Flip the Agent Harness
- Oct 28, 2026Liquid AI releases LFM2.5-24B-A2B: an agent model with 2B active parameters
Build & Ship Production AI Agents Without Boilerplate Code
Start your free 72-hour trial at Hamidun Academy (academy.hamidun.com) — interactive lessons on Claude Code & Cursor, live Tech Radar, and production agent templates.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.