Nvidia releases first open dataset and foundation AI models for medical robots
Nvidia and its partners have published Open-H-Embodiment, the first large open dataset for medical robotics. It contains 778 hours of data covering surgery, ultrasound and colonoscopy. Two models ship alongside it for the first time: GR00T-H for robot control and Cosmos-H-Surgical-Simulator for fast surgical simulation. Together, they are an attempt to assemble a foundation Physical AI stack for medicine.
AI-processed from Hugging Face Blog; edited by Hamidun News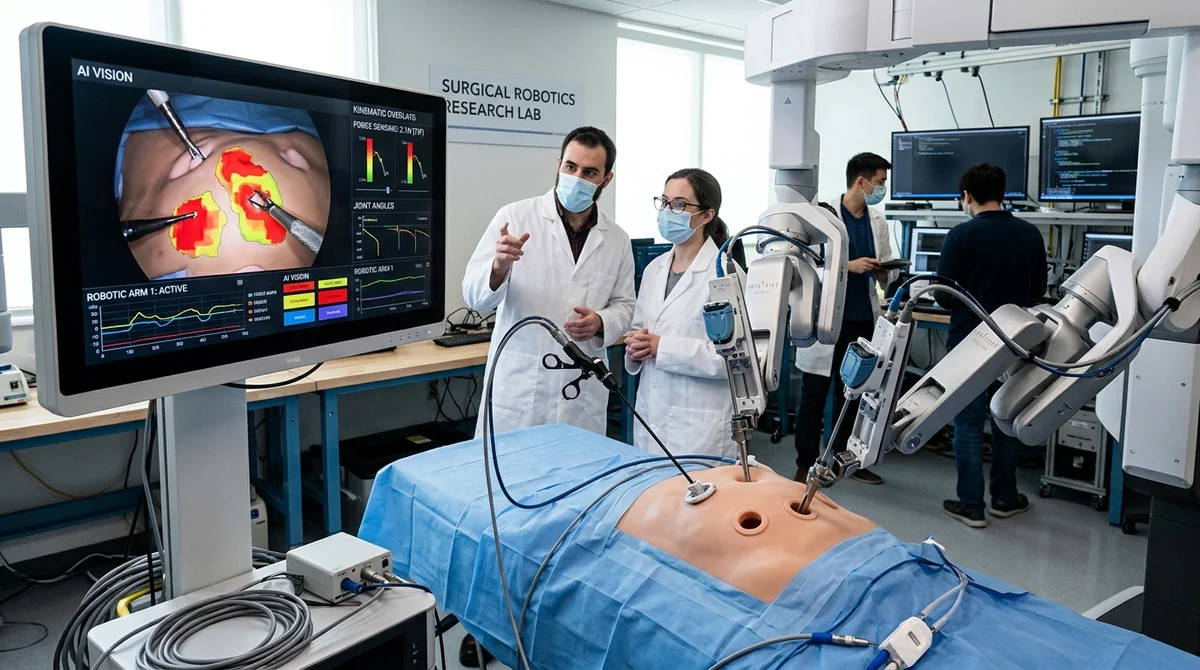
Nvidia, together with the research community, has unveiled Open-H-Embodiment, the first large open dataset for medical robotics, along with two foundation models for surgical scenarios. The package is published on Hugging Face and is meant to push medical AI beyond image analysis toward systems that can act in the physical world.
What was released
The idea behind the release is simple: medicine already has enough models that only recognize scans, segment tissue or classify pathologies. In an operating room, during an ultrasound or a colonoscopy, a machine has to handle an instrument, sense contact with tissue, account for robot kinematics and close the control loop through feedback. Open-H-Embodiment was built for exactly that: a common foundation for training and evaluating Physical AI in medical robotics.
- 778 hours of training data under the CC-BY-4.0 license
- 35 contributing organizations from universities, clinics and industry
- scenarios from surgery, ultrasound and autonomous colonoscopy
- data from simulation, training-rig exercises and real procedures
- support for commercial and research robotic platforms
For the market, format matters as much as volume. The dataset combines vision, force, kinematics and different robot embodiments in one open collection, so teams can compare approaches on a shared base rather than on closed, local collections. Nvidia, Johns Hopkins, Technical University of Munich, Stanford and dozens of other teams take part, so this is not a one-off publication but an attempt to set an industry standard.
How the models work
Alongside the dataset, Nvidia released GR00T-H, a Vision-Language-Action model for surgical robotics trained on roughly 600 hours of Open-H-Embodiment data. It is essentially a policy model: it takes visual and text context and translates it into robot actions. The authors specifically stress that they introduced a shared normalized action space across different robots, dedicated projections for each robot's kinematics, and training on relative instrument movements. The prototype has already completed a full suture in the SutureBot benchmark, meaning it handled a long sequence of precise actions rather than a short gesture.
The second part of the stack is Cosmos-H-Surgical-Simulator, a world foundation model for action-conditioned simulation of surgery. It was fine-tuned on Open-H-Embodiment to generate plausible video of an operation directly from the robot's kinematic actions, including complex effects such as soft-tissue deformation, glare, blood and smoke. The practical gain is clear: 600 runs in this simulator take about 40 minutes, versus roughly two days on real bench tests. Fine-tuning used 64 A100 GPUs and about 10,000 GPU-hours, so this is serious infrastructure groundwork, not a lab demo clip.
What comes next
The most interesting part of the story is the attempt to move medical robotics from a "model sees" mode to a "model acts and generalizes" mode. An open dataset plus two foundation models give researchers a common stack for sim-to-real experiments, synthetic data generation and skill transfer between different robots. This matters especially in surgery, where large, high-quality datasets are expensive to collect and a control error costs far more than in ordinary computer vision.
"Surgical robotics needs its own ChatGPT moment."
That is how the authors describe the goal of the second version of Open-H-Embodiment. The next stage is not just better instrument control but autonomy with elements of reasoning: systems should be able to explain steps, plan long procedures, adapt to failures and learn from annotated trajectories that specify intent, outcomes and error types. If the community really does assemble such reasoning-ready data, medicine could get not yet another narrow algorithm but a platform for more general-purpose robotic assistants.
What it means
For the AI market, this is an important shift: medicine is starting to openly build not just recognition models but a foundation layer for Physical AI, where data, policy models and simulators ship as a package. If the approach takes off, startups, labs and robot makers will have a common starter kit to speed up research, cut testing costs and move faster from prototypes to clinically useful systems.
- Nov 2, 2026Anthropic needs to grow revenue 32% a year to cover $850 billion in contracts
- Nov 2, 2026TensorFold 1.2.0 boosts Qwen3.8-27B throughput on M3 Ultra by 44.2% at 16 streams
- Nov 1, 2026Local models lose to Opus and Codex: 0.21 on a MacBook versus 1.00 for Codex
- Nov 1, 2026Habr author fine-tunes YOLOv8l on dental X-rays and pushes mAP50 to 0.642
Key Questions Answered
What was released?
The idea behind the release is simple: medicine already has enough models that only recognize scans, segment tissue or classify pathologies. In an operating room, during an ultrasound or a colonoscopy, a machine has to handle an instrument, sense contact with tissue, account for robot kinematics and close the control loop through feedback. Open-H-Embodiment was built for exactly that: a common foundation for training and evaluating Physical AI in medical robotics. 778 hours of training data under the CC-BY-4.0 license 35 contributing organizations from universities, clinics
How the models work?
Alongside the dataset, Nvidia released GR00T-H, a Vision-Language-Action model for surgical robotics trained on roughly 600 hours of Open-H-Embodiment data. It is essentially a policy model: it takes visual and text context and translates it into robot actions. The authors specifically stress that they introduced a shared normalized action space across different robots, dedicated projections for each robot's kinematics, and training on relative instrument movements. The prototype has already completed a full suture in the SutureBot benchmark, meaning it handled a long seque
What comes next?
The most interesting part of the story is the attempt to move medical robotics from a "model sees" mode to a "model acts and generalizes" mode. An open dataset plus two foundation models give researchers a common stack for sim-to-real experiments, synthetic data generation and skill transfer between different robots. This matters especially in surgery, where large, high-quality datasets are expensive to collect and a control error costs far more than in ordinary computer vision. "Surgical robotics needs its own ChatGPT moment." That is how the authors describe the goal of t
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.