What Is RAG: How ChatGPT and Other AI Models Stop Making Things Up
Habr AI has published a clear explainer on RAG, an approach that reduces LLM hallucinations by searching documents before the model answers. The focus is the reranker: a layer that re-sorts the retrieved fragments and leaves the model with genuinely relevant context. The core idea is simple: answer quality depends not only on the model, but also on which pieces of knowledge the system feeds it before generation.
AI-processed from Habr AI; edited by Hamidun News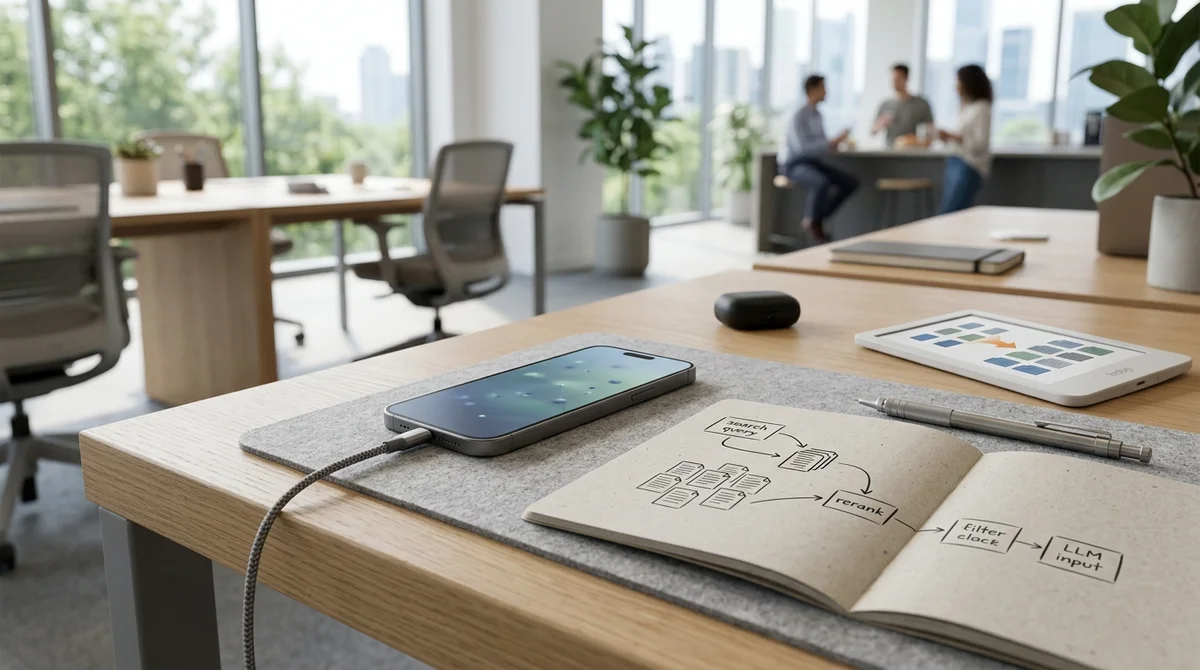
Habr AI has explained how RAG and rerankers help ChatGPT and other language models answer from documents instead of inventing facts. The approach centers not only on searching a knowledge base, but also on a reranker that picks the context fragments that are genuinely relevant.
What is RAG and why does it matter?
RAG is an approach that helps language models look for answers in documents rather than make up facts from their weights. This is critical for enterprise scenarios, where model errors quickly become a risk.
How does a reranker help reduce hallucinations?
The reranker decides which context fragments are actually worth showing to the model. This improves answer quality, because the model sees only the most relevant information.
- Nov 1, 2026Local models lose to Opus and Codex: 0.21 on a MacBook versus 1.00 for Codex
- Nov 1, 2026Kimi scores 96.2% on a 1C database analytics test and emerges as a fallback if Claude access is blocked
- Nov 1, 2026OpenAI Rewrites GPT Behavior Rules: Five Values and a Chain of Command
- Nov 1, 2026Google admits AI Mode cuts search revenue, shares fall 15%
Key Questions Answered
What is RAG and why does it matter?
RAG is an approach that helps language models look for answers in documents rather than make up facts from their weights. This is critical for enterprise scenarios, where model errors quickly become a risk.
How does a reranker help reduce hallucinations?
The reranker decides which context fragments are actually worth showing to the model. This improves answer quality, because the model sees only the most relevant information.
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.