MarkTechPost
AI news source. Articles are auto-selected and adapted by Hamidun News editors.
Latest publications
Baidu releases Qianfan-OCR — a 4B model for document recognition and understanding
Baidu unveiled Qianfan-OCR, a single 4B model that parses document structure, recognizes text, and extracts tables or answers questions on request.
MarkTechPost showed how to build an LLM system with self-evaluation, confidence, and web search
MarkTechPost presented a practical uncertainty-aware LLM setup: the model first answers and estimates its confidence, then checks itself and triggers web search when uncertain.
GitAgent offers a unified AI agent format for LangChain, AutoGen, and Claude Code
GitAgent proposes storing an AI agent's logic, memory, and rules in a Git repository, then exporting the same agent to LangChain, AutoGen, Claude Code, and other environments.
Google releases colab-mcp: how agents automate Colab notebooks in production
Google unveiled an open-source colab-mcp server for managing Colab notebooks via MCP: agents can add cells, execute code, and build resilient workflows without manual routine.
Yann LeCun Presents LeWorldModel — JEPA Model Without Representation Collapse from Pixels
Yann LeCun's team unveiled LeWorldModel — a world model that learns directly from pixels with two loss functions, avoids representation collapse, and plans up to 48 times faster than alternatives.
HKUDS Detailed OpenSpace — Self-Evolving Skill Engine for AI Agents
HKUDS demonstrated how OpenSpace transforms AI agents into self-learning systems: the engine preserves skills after each task, reuses them, and significantly reduces token consumption.
Nvidia introduced PivotRL — a framework for AI agents with 4x savings in rollout steps
Nvidia showed PivotRL — an approach to fine-tuning AI agents that preserves quality outside the training domain and achieves comparable accuracy to E2E RL with four times fewer rollout steps.
Google Introduces TurboQuant: 6x KV-cache Compression for LLMs Without Accuracy Loss
Google Research unveiled TurboQuant — an algorithm that compresses the KV-cache of large language models by at least six times and accelerates attention computation up to 8x without quality degradation.
MolmoWeb-4B by Ai2: A Web Agent That Sees Websites Like Humans, Without HTML Parsing
Ai2 released MolmoWeb-4B — an open-source multimodal web agent that controls a browser using only screenshots, without access to HTML or DOM trees.
Tencent Releases Covo-Audio — 7B Model for Voice Dialogs and Audio Reasoning
Tencent AI Lab has open-sourced Covo-Audio — a 7B audio model that accepts continuous speech, responds with voice, and targets real-time dialogs and reasoning.
Qwen3.5: Running Reasoning-Models in GGUF and 4-Bit Format via Colab
A Colab pipeline is presented for running Qwen3.5 reasoning-models, distilled in Claude style: with one setting you can switch between the 27B GGUF and a lightweight 2B 4-bit version.
Google Releases Gemini 3.1 Flash Live for Voice AI Agents and Multimodal Dialogue
Google opened preview access to Gemini 3.1 Flash Live — a model for voice and visual AI agents with low latency, tool support, and more natural dialogue.
IWE and OpenAI: How to Turn Markdown Notes into a Knowledge Graph for AI Agents
Using IWE as an example, we showed how to build a local knowledge graph from markdown, connect OpenAI function calling, and construct an agentic RAG with relationship traversal between notes.
Google explained the difference between Google-Agent and Googlebot for AI access and indexing
Google described how the new Google-Agent differs from Googlebot: the first performs actions on sites at user request, the second automatically crawls the web for indexing.
Amazon-affiliated researchers presented A-Evolve for automatic evolution of AI agents
Researchers affiliated with Amazon presented A-Evolve — a system that automates AI agent development and replaces manual tuning with state evolution and self-correction.
Agent-Infra Introduces AIO Sandbox — Unified Environment for AI Agents with Browser and Shell
Agent-Infra released open-source AIO Sandbox — a containerized environment where browser, shell, shared file layer, and MCP are integrated in a single runtime for AI agents.
Cursor releases TypeScript SDK for coding agents with cloud sandboxes and token-based pricing
Cursor has opened the public beta of its TypeScript SDK: developers can now run coding agents locally, in the cloud, or on their own workers—with sandboxed VMs, subagents, hooks, and token-based billing.
Alibaba Releases Qwen3.5-Omni — Native Multimodal Model for Text, Audio, and Video
Alibaba has unveiled Qwen3.5-Omni — a native omnimodal model that understands text, images, audio, and video in a single architecture and can respond with voice in real time.
OpenAI Released Privacy Filter: Open Model for Removing Personal Data
OpenAI published Privacy Filter — an open-source model for automatic detection and replacement of personal data, working directly in the browser without server infrastructure.
OpenAI and Promptflow: How to Build an LLM Pipeline with Tracing and Quality Evaluation
The guide shows how to build an LLM pipeline in Google Colab using Promptflow, Prompty, and OpenAI with secure key configuration, run tracing, and built-in quality evaluation.
Meta FAIR Releases NeuralSet — Python Package for Connecting Neural Data and AI Models
Meta FAIR opened NeuralSet — a Python framework that combines fMRI, M/EEG, spikes, and Hugging Face embeddings into a single PyTorch pipeline for Neuro-AI research.
The Qwen team released FlashQLA: accelerating linear attention up to 3× on NVIDIA Hopper
QwenLM released FlashQLA — a CUDA kernel library for Gated Delta Network that delivers up to 3× performance gain on NVIDIA Hopper GPU for pretraining and agentic inference.
OpenAI Privacy Filter: How to Build a Production Pipeline for PII Detection and Masking
The OpenAI Privacy Filter guide breaks down a complete pipeline for detecting and masking personal data — from model loading to automatic text redaction.
DeepSeek, Google, and Meta: 10 Techniques for LLM KV-Cache Compression to Reduce Inference Memory
KV-cache has become a memory hog for large LLMs, and a new survey reveals 10 approaches — from H2O and SnapKV to TurboQuant and DeepSeek's MLA — that reduce memory consumption without complete model restructuring.
Poolside released Laguna XS.2 and M.1 — open models for agentic programming
Poolside unveiled two Laguna models for agentic coding: the open XS.2 runs locally, while the more powerful M.1 is designed for long tasks with code edits, tests, and terminal work.
LlamaIndex ParseBench: How to Test Document Parsing via Python and Hugging Face
A practical walkthrough shows how to build a document parser evaluation pipeline using the LlamaIndex ParseBench dataset: load PDFs from Hugging Face, compare extracted text, and measure quality.
smol-audio from Deep-unlearning: A collection of Colab notebooks for audio model fine-tuning
Deep-unlearning released smol-audio — a collection of Colab-compatible notebooks for fine-tuning Whisper, Parakeet, Voxtral, Granite Speech and other audio models.
Top 10 Physical AI Models Controlling Real Robots in 2026
Over 18 months, the gap between LLMs and real robotics has narrowed dramatically: physical AI models are already operating in factories, warehouses, and research laboratories.
Hugging Face and Gemma 3 1B: Building a Production-Ready Generation Pipeline in Colab
A breakdown of how to run Gemma 3 1B Instruct in Colab via Hugging Face Transformers: with secure authorization, chat templates, and a reproducible inference pipeline.
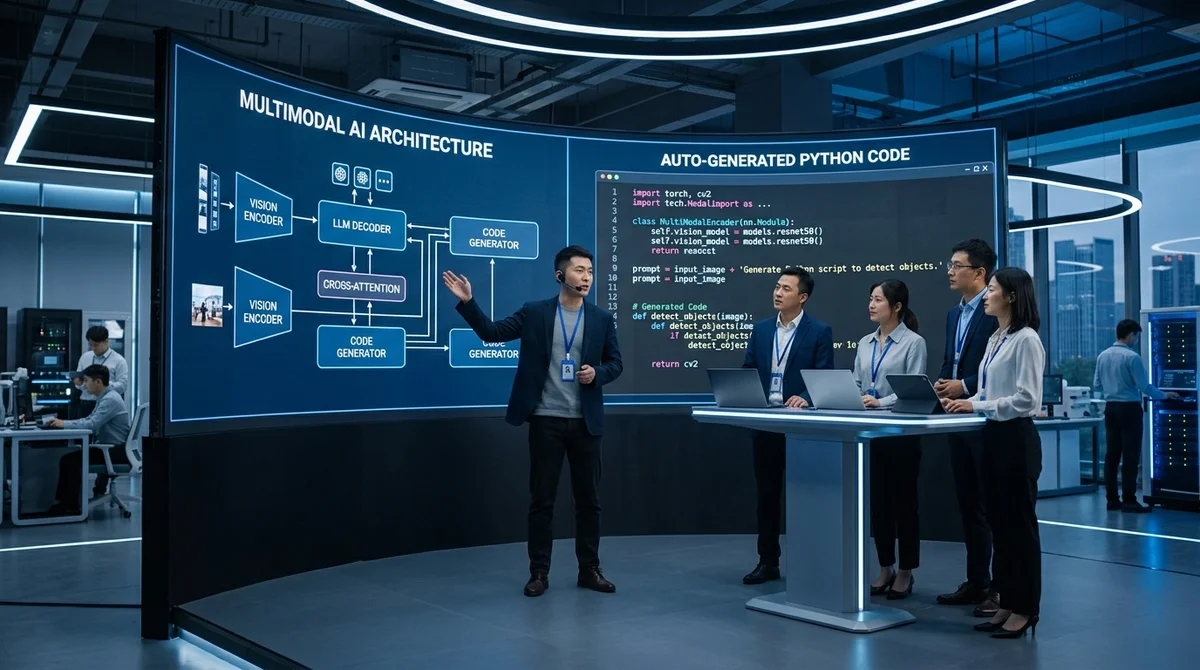
Z.ai releases GLM-5V-Turbo — native multimodal model for visual programming
Chinese lab Z.ai has released GLM-5V-Turbo — a model that recognizes architectural diagrams and screenshots, then immediately generates working code for agentic engineering systems.