How Hugging Face Builds Scalable Web Apps with OpenAI's Privacy Filter
Hugging Face has walked through how to turn OpenAI Privacy Filter into real web products rather than just a text-redaction model. The example includes three apps: a PDF and DOCX viewer that highlights PII, a screenshot anonymizer built on OCR, and a pastebin that publishes an already masked version of the text and reveals the original only through a private link. The common idea is to detect and mask personal data locally first, and only then pass the text, document or screenshot further down an AI pipeline.
AI-processed from Hugging Face Blog; edited by Hamidun News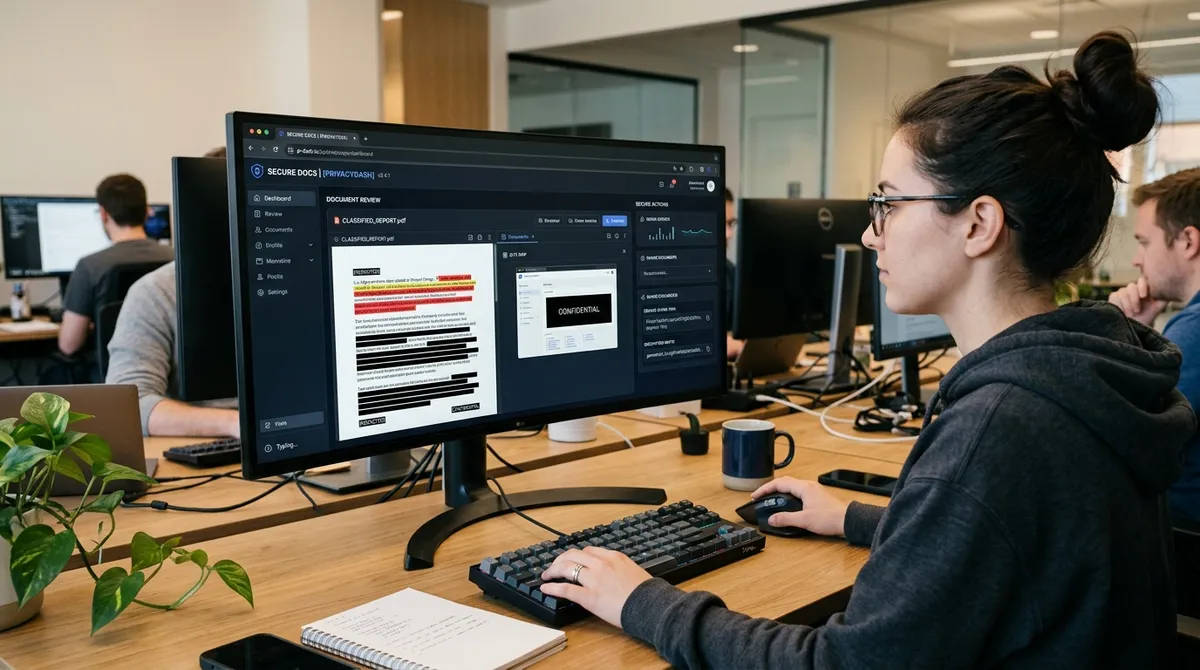
A few days after OpenAI released its Privacy Filter model, the Hugging Face team showed not an abstract presentation but three working scenarios in which the tool becomes a full-fledged web application. The idea is simple: first find and mask personal data locally, and only then pass the text, document or screenshot further down the AI pipeline. For teams building interfaces around sensitive data, this matters more than yet another chat demo, because the question is not only model quality but also how to embed it in a real product without extra infrastructure.
OpenAI released Privacy Filter itself on April 22, 2026. It is an open-weight model for finding and redacting PII in text, licensed under Apache 2.0, so you can run it in your own environment, fine-tune it for your own cases and use it in commercial products.
The model has 1.5 billion parameters, but only about 50 million are active, and its context reaches 128 thousand tokens. It labels text in a single pass and looks for eight types of sensitive entities: private person names, addresses, email, phone numbers, URLs, dates, account numbers and various secrets such as passwords or API keys.
According to OpenAI, the model scores an F1 of 96% on the PII-Masking-300k benchmark, and 97.43% on the corrected version of the dataset. One important detail: it is not a text generator but a specialized token classifier, so it suits fast privacy tasks in logs, documents, indexes and labeling pipelines.
Hugging Face's first example is Document Privacy Explorer. The user uploads a PDF or DOCX and gets the document back with PII fragments highlighted, a category filter and summary statistics at the top. Thanks to the long context, the model can process a large document whole, without splitting it into chunks and stitching the results back together, so character offsets match what the user sees in the interface.
The team specifically stresses that this reader interface was easier to write by hand in HTML and JavaScript than to assemble from ready-made UI blocks. The server side stays compact: a single endpoint via gradio.Server accepts the file, extracts the text, runs it through Privacy Filter and returns the text, the detected spans and the statistics.
The second scenario is Image Anonymizer for screenshots and images. The pipeline is a bit more complex here: first OCR via Tesseract extracts the text and word coordinates, then Privacy Filter identifies the sensitive fragments, and after that the backend maps the detected spans back to rectangles on the image. The user gets not just a blurred-out screenshot but an interactive canvas: black boxes can be toggled by category, moved, drawn manually and exported as a finished PNG without sending the changes to the server again. For private scenarios this is a strong argument: all post-processing stays in the browser, and the model is needed only for the initial detection step.
The third example is SmartRedact Paste, essentially a pastebin for sensitive text. The user pastes a log, an email or a ticket and gets two links: a public version with masks such as PRIVATE_EMAIL and PRIVATE_PERSON, and a private link with a token, where the original can be seen with the detected fragments highlighted. This example shows well why Hugging Face uses gradio.
Server specifically. Everything related to the model goes through the @server.api queue, while ordinary pages and paste viewing are served by plain FastAPI routes in the same process.
This lets the service combine custom URLs, a token gate for private viewing and a single detection function available from both the browser and a Python client. The article notes that the whole service, including storage, fits in roughly 200 lines of application code.
The main takeaway from these examples is not that Gradio can show nice demos, but that privacy infrastructure is starting to look like a normal product layer. Hugging Face suggests a simple architecture rule: send heavy model operations to gradio.Server queues, and keep everything else, such as pages, file delivery, cheap reads and token checks, on ordinary FastAPI routes. This setup scales without duplicating backend code and lets you build custom interfaces instead of boilerplate forms. For the market, it is a signal that local filtering of personal data is no longer a task only for large enterprise teams.
At the same time, OpenAI explicitly warns that Privacy Filter is not a compliance certification and not a replacement for policy review. Legal, medical and financial scenarios still require human review, evaluation on domain data and careful threshold tuning. But as a basic building block for secure AI applications, it is already a very practical tool.
- Nov 2, 2026Meta's Muse assistant keeps dossiers on loved ones and gets root on Ubuntu by default
- Nov 1, 2026Local models lose to Opus and Codex: 0.21 on a MacBook versus 1.00 for Codex
- Nov 1, 2026Kimi scores 96.2% on a 1C database analytics test and emerges as a fallback if Claude access is blocked
- Nov 1, 2026OpenAI Rewrites GPT Behavior Rules: Five Values and a Chain of Command
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.